
Lecture
Это окончание невероятной информации про машинное обучение на больших данных .
...
results
of the schoolchildren. For each schoolchild, the grading results for all problems are known.
It is necessary to calculate how many schoolchildren will get at least K points if
1000000 schoolchildren take the exam.
Note that it is not possible to reliably find the probability of solving
a specific set of problems, but let us assume that it is possible to reliably estimate
the probability of solving one problem.
Input format:
The first line gives the number K — the number of points needed to successfully pass
the test. The second line contains 5 natural numbers — the points for the problems. The first number corresponds
to the points for the first problem, the second — for the second, and so on.
Next follow 100 lines. Each line contains 5 numbers indicating whether the
correspondingly numbered problem was solved or not. The first position in the line indicates whether the
first problem was solved, the second whether the second was solved, and so on. If the problem was solved, the line will
contain 1; if not — 0.
Output format:
On the single line, print the expected number of people who will successfully pass
the same test if it is taken by 1000000 schoolchildren.
METHOD OF EVALUATING THE WORK:
The following code in Python is used to generate a unique test case and check the
result. The function generate returns a set of tests and the correct answers:
def generate():
num_tests = 10
tests = []
for test in range(num_tests):
num_tasks = 5
points = []
for i in range(num_tasks):
points.append(random.randint(1, 100))
sum_points = sum(points)
results = []
for i in range(100):
results.append(' '.join([random.choice(['0', '1']) for i in
range(num_tasks)]))
good_points = random.randint(0, sum_points)
test_case = "{}\n{}\n{}\n".format(good_points, ' '.join([str(point) for
point in points]), '\n'.join(results))
tests.append(test_case)
return tests
def check(reply, clue):
return int(reply) - int(clue) < int(2)
SOLUTION:
We count how many participants solved each problem. From this we determine
the probability of solving a particular problem.
Based on this information, we calculate the probability of solving a particular set
of problems. If this set of problems corresponds to successfully passing the test,
we increase the total probability of successfully passing the test.
An example of a correct program in Python:
01. good_point = int(input())
02. points = list(map(int, input().split()))
03. tasks_res = * 5
04. p = * 5
05. for i in range(100):
06.
sh_res = list(map(int, input().split()))
07.
for j in range(5):
08.
tasks_res[j] += sh_res[j]
09. for i in range(5):
10.
p[i] = tasks_res[i] / 100
11. sum_p = 0
12. for a0 in (0, 1):
13.
for a1 in (0, 1):
14.
for a2 in (0, 1):
15.
for a3 in (0, 1):
16.
for a4 in (0, 1):
17.
if a0 * points + a1 * points + a2 * points + a3
* points + a4 * points >= good_point:
18.
tmp = 1
19.
tmp =(tmp*(1-p )) if a0==0 else (tmp*p )
20.
tmp =(tmp*(1-p )) if a1==0 else (tmp*p )
21.
tmp =(tmp*(1-p )) if a2==0 else (tmp*p )
22.
tmp =(tmp*(1-p )) if a3==0 else (tmp*p )
23.
tmp =(tmp*(1-p )) if a4==0 else (tmp*p )
24.
sum_p += tmp
25. print(int(1000000*sum_p))
When we work with undirected graphs, the following problem often
arises: make the graph as small as possible, but in such a way that all vertices remain connected to each
other. For example, imagine that you want to build a railroad between
several cities, and you were brought a huge map on which all
possible railroad route options and their construction costs are laid out. You want, out of all the routes,
to take the minimally necessary set so that all cities are connected to each other, but
the construction of the railroad network itself costs as little as possible.
Cities and roads form a weighted undirected graph. Cities are the vertices
of the graph, roads are the edges, and road prices are the edge weights. Now our problem has been reduced to pure
mathematics: we need to select a certain set of edges in the graph such that the graph remains
connected, and the total weight of the edges is the smallest possible.
It is easy to notice that in order to connect N cities, we need N−1
roads. It is also clear that if some of the selected roads form a cycle, then it would
have been possible not to build one of the roads in this cycle, but the transportation network would still remain connected.
And since it could have not been built, it means the result could have been obtained more cheaply.
Connected graphs in which the number of edges is one less than the number of vertices and which have no cycles
are called trees. This means we need to obtain exactly a tree, but not just any tree - the
cheapest one. The cheapest tree connecting all vertices of the graph is called a
minimum spanning tree.
In order to build a minimum spanning tree, one can use
Kruskal's algorithm. Its idea is very simple: we will add roads one at a time, starting
with the cheapest one. But if a road connects some cities between which there is already a
route, then this road is useless (it will create a cycle) and we will not take it, but will take
the next road by price. After N−1 steps we will unite all N cities, if this was
possible. Now let's look at the algorithm in a bit more detail. Your task will be to implement it as
a program in Python.
At each iteration of our algorithm, the cities and the roads built so far form
several disjoint trees. Initially these trees are very small, each tree consists of
a single vertex-city, and there are no road-edges at all. Let's number the cities.
We will also number the trees, and for each vertex we will store information about
which tree it belongs to (we need this to know precisely which vertices
do not need to be connected). Initially, each vertex belongs to a tree with the same number
as the vertex itself; we will store this information in a special array, in
which the tree numbers of each vertex will be stored. At each iteration we will
merge two trees into one with an edge; in doing so we will have to change this array to
show that the vertices from the merged trees now belong to one tree.
For example, we can take all the vertices from the second tree (after all, we know the number of this
tree) and indicate that these vertices now belong to the first tree
(for this,
it is enough to write the number of the first tree into the corresponding elements of the array).
Now all that remains for us is to choose which edges to pick. To begin, let's create
an array containing all possible edges, and sort it by weight from smallest to
largest. Now we will go through all the edges in order and choose which of them
to add and which to skip. If an edge connects two vertices of different trees, we
take it into our minimum spanning tree, merging these two trees along the way. If an edge connects
two vertices that already belong to one tree, we skip it and move on to
the next one.
Input format:
The first line of the input file contains two natural numbers N and M - the number
of vertices and edges of the graph respectively 1≤N≤1000,0≤M≤2000. The next M lines contain
the description of the edges, one per line. Edge number i is described by three natural
numbers bi, ei, wi — the numbers of the edge's endpoints and its weight respectively 1≤bi,ei≤N,0≤wi≤100000.
It is guaranteed that the graph consists of a single connected component.
Output format:
Print a single integer — the weight of the minimum spanning tree.
METHOD OF EVALUATING THE WORK:
The following code in Python is used to generate a unique test case and check the
result. The function generate returns a set of tests and the correct answers.
An example of several tests is shown below:
def generate():
num_tests = 10
tests = [("4 4\n1 2 1\n2 3 2\n3 4 5\n4 1 4\n", "7\n"),
("5 10\n4 3 3046\n4 5 90110\n5 1 57786\n3 2 28280\n4 3 18010\n4 5 61367\n4 1
18811\n4 2 69898\n3 5 72518\n3 1 85838\n", "107923\n"),
("2 1\n1 2 10986\n", "10986\n"),
("3 2\n1 3 15891\n3 2 90498\n", "106389\n"),
("10 17\n8 7 83353\n7 10 74636\n7 4 47938\n10 3 4456\n8 1 90055\n3 6 22856\n10 5
84755\n3 9 77963\n5 2 58908\n8 4 44704\n8 3 36890\n8 5 28033\n8 2 30743\n7 10
83866\n7 4 95412\n7 3 48170\n7 6 38877\n","374577\n"),
#...
("6 9\n1 5 1\n5 6 3\n6 2 4\n6 3 5\n5 4 2\n1 4 3\n2 3 6\n1 2 5\n3 4 7\n",
"15\n")]
return tests
def check(reply, clue):
return int(reply) == int(clue)
SOLUTION:
The solution algorithm is described in detail in the problem statement. The problem requires careful
implementation.
01. n, m = map(int, input().split())
02. gr = []
03. tree_num = [i for i in range(n)]
04. for i in range(m):
05.
b, e, w = map(int, input().split())
06.
gr.append((w, b-1, e-1))
07.
08. gr.sort()
09. ans = 0
10. for reb in gr:
11.
if tree_num[reb ] == tree_num[reb ]:
12.
continue
13.
ans += reb
14.
min_num = min(tree_num[reb ], tree_num[reb ])
15.
max_num = max(tree_num[reb ], tree_num[reb ])
16.
for i in range(n):
17.
if tree_num[i] == max_num:
18.
tree_num[i] = min_num
19. print(str(ans))
tree_num — an array in which the i-th position holds the number of the tree that
the i-th vertex currently belongs to
Problem statement. Participants in the team part of the final stage were
required to solve a series of problems analyzing the social network user graph:
predict the age of a user who has not specified it in their profile; predict the region
of the user's residence; guess which of the other social network users
is an acquaintance of the user.
Participants had to write programs in Python. The duration of
the team part of the final stage was
— 3 days (18 clock hours in total).
Participants had access to the Internet and could use their phones and
laptops.
In total, teams were given 3 problems — one for each day. The problem statement
became known to participants on the morning of the corresponding day. Each problem was scored
in points (see below for details).
For each problem, two subgraphs of the real social network
«Odnoklassniki» were prepared:
1. participants
were shown
a specially prepared, cleaned, and
anonymized subgraph;
2. verification of the solution's quality was carried out automatically on the full graph, in
which the data removed from the first graph was present.
For each problem, participants were provided with a working baseline solution with
low efficiency, and the participants faced a choice: to program their own
solution from scratch, which could solve the given problem better, or
to improve the proposed solution. At the same time, it was possible to use the baseline solution
partially, for example only the data model or only the input data parser.
4.1. Description of the source data
In all problems, participants were provided with the user graph
(connections between
users) and a file with demographics
(anonymized data for each
user).
4.1.1. User graph
The graph is stored in a sparse matrix format, where for each connection there is
information about its type (relative, friend, etc.) in the form of a bit mask. Each row
of the matrix corresponds to the friends of one user and has the format:
UserID1 {(FriendID1,mask1), (FriendID2,mask2),…}
The matrix is partitioned by user ID into 16 files, each of which
compressed using the standard GZip compression protocol.
The pairs in the friend list are sorted by friend ID (in ascending order). Example records
from the graph:
102416
{(5362439,0),(7321627,0),(7345280,0),(9939258,0),(9976393,0),(11260492,0),
(11924364,0),(16498676,0),(16513827,0),(21716731,0),(21826340,0),(23746537,0),
(23751503,0),(24412936,0),(24423533,0),(30287856,0),(32321147,0),(34243036,0),
(37592142,0),(39485706,0),(41505243,0),(42791620,0),(52012206,0),(52671472,0),
(54652307,0),(57293803,0),(59242794,0),(59252048,0),(62535397,0),(62563866,0),
(62567154,0),(64588902,0)}
102608
{(4167808,32784),(6019974,32),(6152844,16),(9570536,64),(10699806,33),
(13290514,0),(15064491,128),(16432948,512),(24473204,0),(24655822,0),
(25833075,256),(28000951,64),(30834507,2048),(34567533,16),(35766667,0),
(37385121,0),(40123805,512),(43134386,1024),(45439608,0),(45484652,0),
(47562525,0),(52378153,256),(52403136,512),(52493894,1024),(53483990,0),
(54048767,0),(54286279,2048),(57401158,0),(57956631,0),(58183281,0),
(61117236,32),(61898065,0),(61936634,0),(64512205,512),(65014849,0),
(65112662,0),(65259449,0)}
The following bits can be set in the relationship mask:
1.
Love
2.
Spouse
3.
Parent
4.
Child
5.
Sibling
6.
Uncle or aunt
7.
Relatives
8.
Close friends
9.
Colleagues
10. Classmates
11. Nephew/niece
12. Grandparent
13. Grandchild
14. Fellow student
15. Friendship in the army
16. Adoptive parent
48
17. Adopted child
18. Godfather
19. Godson
20. Playing sports together
In addition to the bits listed above, the relationship mask may or may not have
the zero bit set. This bit plays a purely technical role and has no
physical meaning. As a result, for example, a relationship of type Child can be encoded
by the numbers 16 or 17.
The data was prepared using a tool for storing large
amounts of data, Apache Pig, and contain two corresponding files with headers, allowing
participants to use this tool for preliminary processing/filtering of
the data.
4.1.2. User demographics
Demographic data is provided for the same million users as
the social connection information, in the format of an attribute list:
userId create_date birth_date gender ID_country ID_Location loginRegion
where:
• userId - user identifier
• create_date - date the user account was created (number of milliseconds
since 01.01.1970)
• birth_date - user's date of birth (number of days since 01.01.1970, may
be negative!)
• gender - user's gender (1 - male, 2 - female)
• ID_country - identifier of the country specified in the profile
• ID_Location - identifier of the region/city specified in the profile.
• loginRegion - identifier of the region from which the user most often logs into this
social network (may be absent!)
Example data:
44053078 1166032023073 3067 1 10414533690 2423601 99
12495764 1177932393270 1138
2 10405172143 188081
25646929 1165304175170 3756 2 10414533690 3953941 22
25646999 1160728984480 3884 2 10414533690 241372 120
12495833 1176909723643 3363 2 10414533690 2724941 11
The demographic data is partitioned according to the same scheme as the graph, but is not compressed (it is transferred
as plain text). It can also be processed using the standard
Apache Pig big data storage tool or any other tool
that supports CSV.
Task 4.2.1 «Date of birth»
The fragment of the social graph provided for analysis includes information about
the connections of 100 thousand users that fell within the two-hop neighborhood of a hundred randomly
selected users. Participants are provided with the social network graph files with
all connections and a demographics file, which specifies data for the users, including
age, although age is not specified for all users.
For users who are present in the graph but not present in the demographic data,
the value of their birth_date attribute (date of birth) must be determined.
The results are written to a file in the format:
(
The participants' calculated results are accepted in a file of txt format and
compared with the complete data by a specially written program, which calculates
the discrepancy between the participants' data and the actual data.
The smaller the discrepancy, the higher the team's result is rated according to the scheme
presented further in the «Evaluation methodology» section.
The baseline solution provided to participants (worth 1 point):
1. import random
2. import math
3.
4. from GraphParser import graphParser
5. def printall(res):
6.
for i in range(0,len(res)):
7.
print(res[i])
8.
print("---------")
9. cols = list()
10. cols.append(2)
11. (demog,fd) = graphParser.parseFolder("Task1\\Task1\\trainDemography",0,"",0,
cols)
12. c=1
13. for key, value in demog.items():
14.
print(str(key) + " val "+ str(value))
15.
c+=1
16.
if c==3:
17.
break
18.
19.
#print(demog)
20.
graph = graphParser.parseFolderBySchema("Task1\\Task1\\graph",30,"")
21.
#print(graph )
22.
minBD = 9999999999999999
23.
maxBD = 0
24.
keyVal = 0 #'birth_date'
25.
for key, value in demog.items():
26.
#print(key)
27.
bd = int(value[keyVal])
28.
# print( people)
29.
if bd>maxBD:
30.
maxBD=bd
31.
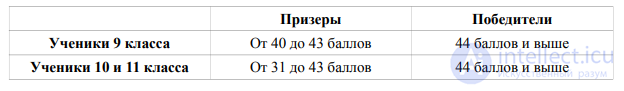
if bd 32. minBD=bd 33. print(minBD) 34. print(maxBD) 35. randCount=15 36. diffSum1 = 0 37. diffSum = *randCount 38. for people in graph : 39. pId = people['from'] 40. if pId not in demog.keys(): 41. print("err for "+str(pId)) 42. continue 43. dateSum = 0 44. totalLen=0 45. maxBDp = 0 46. minBDp = 9999999999999999 47. #print(people['links']) 48. for links in people['links']: 49. 50. pIdr = links['to'] 51. print(links['to']) 52. 53. 54. if pIdr not in demog.keys(): 55. print("err for "+str(pIdr)) 56. continue 57. totalLen+=1 58. bd = int(demog[pIdr][keyVal]) 59. if bd>maxBDp: 60. maxBDp=bd 61. if bd 62. minBDp=bd 63. dateSum+=int(bd) 64. 65. if (totalLen == 0): 66. continue 67. # avg=propBirthDate 68. #else: 69. avg=(dateSum)/(totalLen) 70. 71. if (totalLen>=4): 72. print("TOTAL Len big!"+str(totalLen)) 73. avg=(dateSum-maxBDp-minBDp)/(totalLen-2) 74. else: 75. print("total len small!"+str(totalLen)) 76. avg=(dateSum)/(totalLen) 77. 78. #avg=propBirthDate 79. 51 80. trueVal = int(demog[pId][keyVal]) 81. diffSum1+= abs(trueVal-avg) 82. for ind in range(0,len(diffSum)): 83. avg = random.randrange(minBD,maxBD) 84. diffSum[ind]+= abs(trueVal-avg) 85. 86. print(diffSum1) 87. for ind in range(0,randCount): 88. print(diffSum[ind]) METHOD OF RESULT EVALUATION: To obtain a quantitative evaluation of the correctness of the result, the following was used the following comparator program written in Python: import pandas as pd import numpy as np from random import randint import math dir_name = 'testDemography' files = ['part-v004-o000-r-00000', 'part-v004-o000-r-00001', 'part-v004-o000-r- 00002', 'part-v004-o000-r-00003', 'part-v004-o000-r-00004', 'part-v004-o000-r- 00005', 'part-v004-o000-r-00006', 'part-v004-o000-r-00007', 'part-v004-o000-r- 00008', 'part-v004-o000-r-00009', 'part-v004-o000-r-00010', 'part-v004-o000-r- 00011', 'part-v004-o000-r-00012', 'part-v004-o000-r-00013', 'part-v004-o000-r- 00014', 'part-v004-o000-r-00015'] files = [dir_name + '/' + i for i in files] df = pd.DataFrame() frames = [] for file_name in files: d = pd.read_csv(file_name, sep='\t', names=['id', 'date', 'num', 'bla1', 'bla2', 'bla3', 'bla4', 'bla5']) del d['date'] del d['bla1'] del d['bla2'] del d['bla3'] del d['bla4'] del d['bla5'] frames.append(d) test_data = pd.concat(frames, ignore_index=True) answers = pd.read_csv('results.txt', sep='\t', names=['id', 'num']) def compare(res, test): to_sum = [] for i, row in res.iterrows(): vals = test[test['id'] == row['id']]['num'].values if(len(vals)): stds = [] for v in vals: if ((not math.isnan(v)) and not math.isnan(row['num'])): stds.append(math.pow(v - row['num'], 2)) if(len(stds)): print('stds', stds) to_sum.append(min(stds)) return sum(to_sum) s = compare(answers, test_data) print(s) SOLUTION: First of all, it is necessary to determine that the given task is a regression task, after which one can study the specifics of this task, find correlations between user properties, and search for the best model for working with this data. Hypotheses about the age of a user's friends may also yield important results. Task 4.2.2 «Region» The fragment of the social graph provided for analysis includes information about the connections of 100 thousand users that fell within the two-hop neighborhood of a hundred randomly selected users. Participants are provided with the social network graph files with all connections and a demographics file, which specifies data for the users, including region, although region is not specified for all users. For users who are present in the graph but not present in the demographic data, it is necessary to determine their ID_Location attribute (region). The answer is written to a text file in the format: ( The participants' calculated results are accepted in a file of txt format and compared with the complete data by a specially written program, which calculates the discrepancy between the participants' data and the actual data. The smaller the discrepancy, the higher the team's result is rated according to the scheme, presented in the «Evaluation methodology» section. The baseline solution provided to participants (worth 1 point): 1. import math 2. import sys 3. 4. def bl(graph, locs, fd=False): 5. res = list() 6. count = int(0) 7. 8. for pId,conns in graph.items(): 9. count+=1 10. if count%1000 == 0: 11. print(count) 12. dateSum = 0 13. totalLen=0 14. locIds=dict(); 15. print(pId) 16. try: 17. if locs[pId] != None: 18. continue 19. except: 20. pass 21. if type(conns) == int: 22. conns=[conns] 53 23. for links in conns: 24. totalLen+=1 25. try: 26. frLoc=locs[links] 27. except: 28. continue 29. try: 30. locIds[frLoc]+=1 #int(demog[links]) 31. except: 32. locIds[frLoc]=1 33. 34. resId=0 35. popId=0 36. for locId, total in locIds.items(): 37. if total>popId: 38. popId=total 39. resId=locId 40. 41. res.append([pId,resId]) 42. if (fd): 43. fd.write(str(pId)+'\t'+str(resId)+'\n') 44. return res 45. 46. from GraphParser import graphParser 47. 48. pass 49. cols = list() 50. cols.append("userId") 51. cols.append("ID_Location") 52. (locs,fd) = graphParser.parseFolderBySchema("Task2\\Task2\\trainDemography",0,"","userId", cols, True) 53. cols = list() 54. cols.append("from") 55. cols.append("to") 56. cols.append("links") 57. (graph, fd) = graphParser.parseFolderBySchema("Task2\\Task2\\graph",0,"","from",cols,True) 58. print("data loaded") 59. fdres=open("results.txt",'w') 60. bl(graph,locs, fdres) METHOD OF RESULT EVALUATION: To obtain a quantitative evaluation of the correctness of the result, the following was used comparator program written in Python: import pandas as pd import numpy as np import math import ast test_df = pd.read_csv('task2/test.tsv', sep='\t', names=['id', 'groups']) results_df = pd.read_csv('task2/results.tsv', sep='\t', names=['id', 'groups']) def compare(results, test): #Iterate over all submitters results score = 0 not_found_penalty = -5 false_found_penalty = -5 found_reward = 10 for i, row in test.iterrows(): test_groups = ast.literal_eval(row['groups']) #No such user if(not (any(results.id == row['id']))): score = score + (len(test_groups) * not_found_penalty) continue #Get fit result_groups = ast.literal_eval(results[results['id'] == row['id']] ['groups'].values ) for tg in test_groups: if (tg in result_groups): score = score + found_reward result_groups.remove(tg) test_groups.remove(tg) #Get penalty score = score + (len(result_groups) * not_found_penalty)#not found score = score + (len(test_groups) * false_found_penalty)#false found return score compare(results_df, test_df) SOLUTION: First of all, it is necessary to determine that the given task is a classification task, after which one can study the specifics of the task, find correlations between user properties, and search for the best model for working with this data. Hypotheses about the location_id attribute of the user's friends may also reveal important results, especially for those friends who attended the same school as the user. The second task is similar to the first, although it belongs to a different class of machine learning tasks; thus participants could reuse their work from the first task to solve the second one. Task 4.2.3 «Finding connections» The fragment of the social graph provided for analysis includes information about the connections of 1 million users that fell within the two-hop neighborhood of a hundred randomly selected users. Participants are provided with graph and demographic files for the users. Part of the connections in the provided social graph is hidden, and the participants' task is to reveal them as fully and accurately as possible. The hiding of connections affected only users from the original million, whose ID attribute has a remainder of 7 when divided by 11 (id % 11 == 7); about 10% of the connections for each of these users were hidden. Only connections leading into the original million were hidden. In the prediction, it is sufficient to restore the presence of a connection; its type does not matter. The results of the prediction must be presented in the format of a CSV file of the form: ID_user1 ID_candidate1.1 ID_candidate1.2 ID_candidate1.3 ID_user2 ID_candidate2.1 ID_candidate2.2 The records in the file are sorted by user ID (in ascending order), and then by the predicted relevance of the candidates (in descending order; the relevance itself does not need to be written to the file). Example results: 5111 178542 78754 18807 982346 1346 57243 The participants' results are evaluated using the Normalized Discounted Cumulative Gain metric (Normalized Discounted Cumulative Gain, NDCG), which is used in the industry to evaluate the accuracy of an algorithm for this and similar tasks. The metric is calculated separately for each user for whom there are hidden connections, and then averaged. Records in the results file that are not related to users with hidden connections will not be taken into account when evaluating the result. If for some user no candidates at all are proposed, the metric value for that user will be counted as 0. The baseline solution provided to participants (worth 1 point): 1. # For reading/writing csv files 2. import csv 3. # For working with archives 4. import gzip 5. # For working with the file system 6. import os 7. # Efficient arrays of primitive types 8. import numpy 9. # Working with matrices (counting common friends is implemented as multiplying the graph matrix by itself) 10. import scipy 11. from scipy.sparse import coo_matrix, csr_matrix 12. # Paths to the data 13. dataPath = "./" 14. graphPath = os.path.join(dataPath, "trainGraph") 15. predictionPath = os.path.join(dataPath,"prediction.gz") 16. 17. # Main graph parameters 18. numUsers = 107474 19. numLinks = int(72384968 / 2) 20. maxUserId = 9418031 21. # We will collect data in these arrays. We initialize them in advance with the required size so that 22. # there is no unnecessary copying 23. form = numpy.zeros( (numLinks), dtype=numpy.int32 ) 24. to = numpy.zeros( (numLinks), dtype=numpy.int32 ) 25. data = numpy.ones( (numLinks), dtype=numpy.int32 ) 26. 27. # Here we store the position where the new connection needs to be written 28. current = 0 29. 30. # Iterate over the files in the folder 31. for file in [f for f in os.listdir(graphPath) if f.startswith("part")]: 32. csvinput = gzip.open(os.path.join(graphPath, file), mode='rt') 33. csv_reader = csv.reader(csvinput, delimiter='\t') 34. # Now iterate over the lines in the file 35. for line in csv_reader: 36. user = int(line ) 37. # Parse the ids and friend masks 38. for friendship in line .replace("{(", "").replace(")}", "").split("),("): 39. parts=friendship.split(",") 40. # Write the connection into the arrays and move the pointer 41. form[current] = user 42. to[current] = int(parts ) 43. current += 1 44. 45. # Don't forget to close the file 46. csvinput.close() 47. # Create a matrix from the arrays. Initially the matrix is stored as a list of [i,j,v], but for efficient 48. # further processing we need to convert it to the form [i->[j,v]] 49. fullMatrix = coo_matrix( 50. (data, (form, to)), 51. shape=(numLinks + 1, numLinks + 1)).tocsr() 52. 53. # The arrays are no longer needed, remove them from memory 54. del form 55. del to 56. del data 57. # Compute the transposed matrix (columns and rows swapped) and also convert it to the form [i->[j,v]] 58. reversedMatrix = scipy.transpose(fullMatrix).tocsr() 59. # Since we only need to build the prediction for part of the users, we will zero out the rest of 60. # the original matrix (fill with zeros) 61. for i in range(maxUserId + 1): 62. if i % 11 != 7: 63. ptr = fullMatrix.indptr[i] 64. ptr_next = fullMatrix.indptr[i+1] 65. if ptr != ptr_next: 66. fullMatrix.data[ptr:ptr_next].fill(0) 67. 68. # To keep the zeros from interfering with the multiplication, we clean them out and shrink the matrix 69. fullMatrix.eliminate_zeros() 70. # This is where the main magic happens - by multiplying the matrices we get counters of common friends, 71. # based on which we will build the prediction 72. commonFriends = fullMatrix.dot(reversedMatrix) 73. # Now all that remains is to write it to a file. Open the writers 74. f = open('prediction.csv', 'w') 75. writer = csv.writer(f, delimiter='\t') 76. 77. for i in range(maxUserId + 1): 78. # Two pointers give us the bounds within which the data for this i lies in the matrix 79. ptr = commonFriends.indptr[i] 80. ptr_next = commonFriends.indptr[i+1] 81. # If they are not equal, it means there is data and it can be exported 82. if ptr != ptr_next: 83. # Retrieve the common-friend counters and create an ordering of them from largest to smallest 84. counts = commonFriends.data[ptr:ptr_next] 85. order = numpy.argsort(-counts) 86. 87. # Remember to remove ourselves and our known friends from the prediction 88. mineFriends = set(fullMatrix.indices[fullMatrix.indptr[i]:fullMatrix.indptr[i+1]]) 89. mineFriends.add(i) 90. 91. # Retrieve the friend ids, sort, filter, truncate, and write 92. ids = commonFriends.indices[ptr:ptr_next] 93. writer.writerow([i] + list(filter(lambda x: x not in mineFriends, ids[order]))[:42]) 94. 95. # Don't forget to close the file 96. f.close() METHOD OF RESULT EVALUATION: To obtain a quantitative evaluation of the correctness of the result, the following was used comparator program written in Python: import pandas as pd import numpy as np dir_name = 'testDemography' files = ['part-v004-o000-r-00000', 'part-v004-o000-r-00001', 'part-v004-o000-r- 00002', 'part-v004-o000-r-00003', 'part-v004-o000-r-00004', 'part-v004-o000-r- 00005', 'part-v004-o000-r-00006', 'part-v004-o000-r-00007', 'part-v004-o000-r- 00008', 'part-v004-o000-r-00009', 'part-v004-o000-r-00010', 'part-v004-o000-r- 00011', 'part-v004-o000-r-00012', 'part-v004-o000-r-00013', 'part-v004-o000-r- 00014', 'part-v004-o000-r-00015'] files = [dir_name + '/' + i for i in files] df = pd.DataFrame() frames = [] for file_name in files: print(file_name) d = pd.read_csv(file_name, sep='\t', names=['id', 'date', 'num', 'bla1', 'bla2', 'bla3', 'bla4', 'bla5']) del d['date'] del d['bla1'] del d['bla2'] del d['bla3'] del d['bla4'] del d['bla5'] frames.append(d) result = pd.concat(frames, ignore_index=True) result def dcg_at_k(r, k, method=0): """Score is discounted cumulative gain (dcg) Relevance is positive real values. Can use binary as the previous methods. Args: r: Relevance scores (list or numpy) in rank order (first element is the first item) k: Number of results to consider method: If 0 then weights are [1.0, 1.0, 0.6309, 0.5, 0.4307, ...] If 1 then weights are [1.0, 0.6309, 0.5, 0.4307, ...] Returns: Discounted cumulative gain """ r = np.asfarray(r)[:k] if r.size: if method == 0: return r + np.sum(r[1:] / np.log2(np.arange(2, r.size + 1))) elif method == 1: return np.sum(r / np.log2(np.arange(2, r.size + 2))) else: raise ValueError('method must be 0 or 1.') return 0. def ndcg_at_k(r, k, method=0): """Score is normalized discounted cumulative gain (ndcg) Relevance is positive real values. Can use binary as the previous methods. Args: r: Relevance scores (list or numpy) in rank order (first element is the first item) k: Number of results to consider method: If 0 then weights are [1.0, 1.0, 0.6309, 0.5, 0.4307, ...] If 1 then weights are [1.0, 0.6309, 0.5, 0.4307, ...] Returns: Normalized discounted cumulative gain """ dcg_max = dcg_at_k(sorted(r, reverse=True), k, method) if not dcg_max: return 0. return dcg_at_k(r, k, method) / dcg_max r = [3, 2, 3, 0, 0, 1, 2, 2, 3, 0] ndcg_at_k(r, 7) len(test[test['id'] == 15102006]['num'].values) pd.Series([123, 0], index=['id', 'num']) any(result.id == 115368359) t.to_csv('results.csv', sep='\t', index = False, header = False) def compare(res, test): #Iterate over all submitters results to_sum = [] for i, row in test.iterrows(): # If there is no such id crete with zero if(not (any(res.id == row['id']))): res.append(pd.Series([row['id'], 0], index=['id', 'num'])) for i, row in res.iterrows(): vals = test[test['id'] == row['id']]['num'].values if(len(vals)): stds = [] for v in vals: if (not math.isnan(v)): stds.append(math.pow(v - row['num'], 2)) if(len(stds)): to_sum.append(min(stds)) return sum(to_sum) t1 = result.copy() # t1[t1['id'] == 11536835]['num'] = t1[t1['id'] == 11536835]['num'] + 1 t1.loc[1,'num'] = t1.loc[1,'num'] + 1 t1.loc[2,'num'] = t1.loc[2,'num'] + 2 t1.loc[3,'num'] = t1.loc[3,'num'] - 5 # t1[t1['id'] == 11536835]['num'] s = compare(t1, result) s SOLUTION: As an example solution to the task, whose prediction accuracy needs to be surpassed, logistic regression trained on three features is used: 1. the number of common friends of the two users, 2. the difference in age, and 3. whether the genders match or differ. In addition to improving the algorithm, computational complexity must also be taken into account, which requires not only qualitatively improving the efficiency of the baseline solution, but also managing to compute the results for all users in time. Therefore, for an efficient solution it is necessary to select only those features for inclusion in the model that have a sufficiently high correlation with the friendship of users. This requires participants to formulate hypotheses about which factors have a high correlation, and which — have a low one, and to test the hypotheses on the provided data. For each of the tasks, a comparator program (mentioned above) was written, which compares the participants' solution with the complete data, which was not disclosed and is available only to the Olympiad jury. The greater the discrepancy between the participants' results and the complete data, the lower the participants' score. Thus, checking the participants' submissions and the amount of points awarded were fully automated. The maximum score of the final stage for the team portion could be 56 points. The maximum score for the tasks was distributed as follows: • Task 1 — 10 points; • Task 2 — 16 points; • Task 3 — 30 points. To calculate the number of points awarded to participants, logistic regression with rounding to a whole number of points was used, in which the maximum score corresponded to a result level 4 times better than the baseline solution, and the minimum score (1 point) was awarded for a result level equal to the proposed baseline solution. 0 points were awarded if no result was shown (the team did not submit a valid solution on time) or if the accuracy of the result was lower than the baseline solution. In the final stage of the Olympiad, a participant's score consists of two parts: they receive points for the individual solution of tasks in the subjects (mathematics, computer science) and for the team solution of the practical task. The participant's final Olympiad score is obtained using the following formula: S=S1+S2 , where S1 — the number of points earned within the individual part of the final stage (maximum — 24 points); S2 — the number of points earned within the team part of the final stage (maximum — 56 points). Criteria for determining the winners and runners-up: 4.3. Scoring methodology
5 Criteria for determining the winners and runners-up of the final stage
Продолжение:
Часть 1 Machine Learning on Big Data: Theory and Worked Examples
Часть 2 Problem 3.2.5 «Minimum Spanning Tree» (4 points) - Machine Learning

Comments