We are used to thinking that the main "channel" through which sound reaches the brain is the ears. Practically all the animals we meet in everyday life or see in zoos react to our presence by turning their ears: cats, dogs, elephants or fennec foxes.
There are also animals that have no ears. This does not make them deaf. The range of sounds that some animals can perceive differs greatly from the "human" one. We will continue talking about all this below.
If animals have no ears, how do they sense sounds?
Grasshoppers, like crickets, use their front legs as an audio channel; on them sits a sensitive membrane. This "sensor" can pick up sound waves with an amplitude equal to the diameter of a hydrogen atom. Grasshoppers of some species can sense the slightest changes in their surroundings, including seismic activity, and move to a safe place long before earthquakes.
Fish also have no ears in the usual sense (surely, if they had them, the streamlined shape of the body would be badly disrupted). But these aquatic dwellers have excellent hearing: fish sense sound vibrations through small openings that run along the whole body from head to tail. All the sound waves picked up by these receptors are converted into impulses, which then pass to the swim bladder. This organ, acting as a sound amplifier, transmits the sound to the inner ear (which is very similar in structure to the human one), and then the signal is processed by the brain.
Whales, for their part, receive audio information through the throat and then through a special canal leading to the inner ear. Although, according to an alternative version, whales have an auditory opening that opens behind the eye.
A crocodile does have ears, but they cannot be seen, because its outer ear is closed by a membrane when it dives into the water. The auditory openings themselves are protected on the outside by a bony ridge. The middle ear of crocodiles consists of just one bone, the stapes, which conducts sound to the inner ear. Some scientists believe that crocodiles hear perfectly well underwater, although they probably simply perceive water vibrations with their tactile receptors.
Ants are somewhat similar to grasshoppers in their perception of sound: they have special sensors on their legs and antennae that pick up changes in vibrations. Moreover, ants sense vibrations not only in the air but also through surfaces such as trees, leaves and so on. An ant's hearing organs do not need external structures like, for example, the human ear, since ants have no need to catch sound waves flying through the air. To perceive audio information, ants have so-called scolopidia, string-like organs stretched between the insect's skeleton and a membrane. This system turns oscillations and vibrations into nerve impulses.
How animals hear music
Admit it: those of you who have a cat or dog at home have tried at least once in your life to gauge your pet's reaction to the sound of some piece of music or a film. Scientists have seriously considered the question of how animals perceive music, and they agree on one thing: like us, animals can divide music into music they like and music they find unpleasant.
Zoopsychologists point out that a more precise answer is simply impossible to obtain, because even people perceive music differently. The range of sound perception in animals is different, and one should not forget about the emotions and associations that a particular piece of music evokes. (We have already written about how music works with human emotions.)
The scientist Charles Snowdon asserts that animals do not hear music the way we do. Pets' hearing is much keener than ours, and the range of sounds perceived by dogs and cats is wider than that of humans. Therefore animals do not "distinguish" (in the sense familiar to us) rock, reggae or hip-hop. For them, human music is a whole ocean of sounds and noises, not always pleasant, and not always audible to humans themselves.
But the American composer David Teie has composed relaxing music for cats. The Washington Post immediately ran an experiment ( https://www.washingtonpost.com/video/entertainment/listen-this-music-is-scientifically-proved-to-appeal-to-cats/2015/10/15/31ec6f54-6e9b-11e5-91eb-27ad15c2b723_video.html and checked how animals react to such music.
In his "feline" compositions Teie, for example, samples the sound of a snare drum and speeds it up to the frequency of a cat's purr. As the composer himself believes, if you simply record something resembling purring, the furry audience quickly loses interest. So Teie tries to "tickle their brains" so that the cats think: "I don't know what this is, but I definitely like it!"
The composer studied oscillograms of cat purring and found that each individual sound consists of two: double beats resembling a quickened heartbeat. Humans cannot hear them, but cats can.
Then a "part for mewing kittens" in a very high register was layered over the "purring" ones. Teie played two notes on the violin and then transposed them up two octaves on a computer. Incidentally, the cello in "music for cats" allows people, too, to enjoy such pieces, but first you have to get used to the background purring.
The cellist Teie has been writing music for cats since 2003; in this unusual way he wants to formulate his Universal Theory of Music, according to which music, bypassing consciousness, touches deep emotions, using for this the sounds that surround the fetus in the mother's womb, when the brain has not yet formed.
This music, in his opinion, works equally well for people and for animals. As Teie believes, it is no coincidence that music which a person finds relaxing matches in tempo the resting pulse of his mother, while the sound spectrum of the violin, the most popular classical instrument, matches the spectrum of the female voice. He even conducted an experiment on monkeys and published a detailed report.
So, several years later, David Teie recorded the first album of relaxing music for cats, whose effectiveness he tested on animals at the cat cafe "Cats and Whiskers". It is still unclear what emotions this music evokes in cats, but the promo video for the cat music turned out very touching.
So now, when leaving home, you should play for your pets not Guns N’ Roses; it is better to use David Teie's invention and not hurt their furry ears.
Many people have noticed that dogs, hearing certain music, may sing along, whine and howl. Experiments show that when listening to the same music through an amplifier with speakers or through headphones, dogs react to it in the same way. Most likely, the animal likes the music if it shows no aggression and sits calmly. And by using headphones you can please your pet when those around you do not want to listen to loud music. For this it is better to use lightweight closed-back on-ear headphones. It is good if the headband has telescopic adjustment
Unlike humans, animals do not perceive a musical composition as something whole and unified. They hear particular sounds, which are often pleasant to their ears. Animals also have a developed sense of rhythm, which helps in training them. To certain music they are able to reproduce movements practiced in training. Since dogs can hear high-frequency sounds, special whistles are used in training them.
The effect of music on animals is not always positive. Heavy aggressive music causes hysteria in hens and reduces milk yields in cows. Elephants cannot tolerate such music at all and may leave their home. Modern music can cause animals to have fits of panic and neurosis. A funny incident happened with the dog of a London organist at a choir rehearsal. The dog growled loudly at the choristers who sang off-key, thereby earning the attention of the famous composer Edward William Elgar. He dedicated one of the Enigma Variations to the remarkable dog.
Classification of Domestic Cat Sounds Using Features Derived from Deep Neural Networks
The domestic cat (Felis catus) is one of the most attractive pets in the world, and it makes mysterious sounds depending on its mood and the situation. In this article we deal with the automatic classification of cat sounds using machine learning. The machine learning approach to classification requires class-labeled data, so our work begins with the creation of a small dataset named CatSound in 10 categories. Along with the original dataset, we increase the amount of data using various audio augmentation methods to help our classification task. In this study we use two types of learned features from deep neural networks: one from a convolutional neural network (CNN) pretrained on music data via transfer learning, and the other from an unsupervised convolutional deep belief network (CDBN) trained solely on the collected set of cat sounds. In addition to conventional GAP, we propose an efficient pooling method called FDAP for learning a number of important features. In FDAP, the frequency dimension is roughly divided, and then average pooling is applied within each division. For classification we used five different machine learning algorithms and their ensemble. We compare the classification performance with respect to the following factors: the amount of data increased through augmentation, the learned features from the pretrained CNN or the unsupervised CDBN, conventional GAP or FDAP, and the machine learning algorithms used for classification. As expected, the proposed FDAP features with a larger amount of data increased through augmentation, combined with the ensemble approach, gave the best accuracy. Moreover, the learned features from both the pretrained CNN and the unsupervised CDBN give good results in the experiment. Thus, with a combination of all these positive factors, we obtained the best result: 91.13% in accuracy, 0.91 in F1 score and 0.995 in area under the curve (AUC). the learned features from the pretrained CNN or the unsupervised CDBN, conventional GAP or FDAP, and the machine learning algorithms used for classification. As expected, the proposed FDAP features with a larger amount of data increased through augmentation, combined with the ensemble approach, gave the best accuracy. Moreover, the learned features from both the pretrained CNN and the unsupervised CDBN give good results in the experiment. Thus, with a combination of all these positive factors, we obtained the best result: 91.13% in accuracy, 0.91 in F1 score and 0.995 in area under the curve (AUC). the learned features from the pretrained CNN or the unsupervised CDBN, conventional GAP or FDAP, and the machine learning algorithms used for classification. As expected, the proposed FDAP features with a larger amount of data increased through augmentation, combined with the ensemble approach, gave the best accuracy. Moreover, the learned features from both the pretrained CNN and the unsupervised CDBN give good results in the experiment. Thus, with a combination of all these positive factors, we obtained the best result: 91.13% in accuracy, 0.91 in F1 score and 0.995 in area under the curve (AUC). The proposed FDAP features with a larger amount of data increased through augmentation, combined with the ensemble approach, gave the best accuracy. Moreover, the learned features from both the pretrained CNN and the unsupervised CDBN give good results in the experiment. Thus, with a combination of all these positive factors, we obtained the best result: 91.13% in accuracy, 0.91 in F1 score and 0.995 in area under the curve (AUC). The proposed FDAP features with a larger amount of data increased through augmentation, combined with the ensemble approach, gave the best accuracy. Moreover, the learned features from both the pretrained CNN and the unsupervised CDBN give good results in the experiment. Thus, with a combination of all these positive factors, we obtained the best result: 91.13% in accuracy, 0.91 in F1 score and 0.995 in area under the curve (AUC).
1. Introduction
The sound production and perception systems of animals have evolved to help them survive in their environment. From an evolutionary point of view, the intentional sounds made by animals must differ from random environmental sounds. Some animals have special sensory abilities, such as vision, sight, feeling and awareness of natural changes, compared with humans. Animal sounds can be useful to people in terms of safety, prediction of natural disasters and intimate communication, if we can recognize them correctly.
In recent years, data-driven machine learning for acoustic signals has been of great interest to researchers, and some studies have been carried out on the classification of animal sounds [ 1 , 2 ] and the identification of animal populations based on their sound characteristics [ 3 ]. The sound classification of marine mammals and its impact on marine life were studied in [ 4 , 5 ]. Several studies [ 6 , 7 , 8 , 9 , 10 , 11 , 12 ] focused on the identification and classification of bird sound and related problems. In the study [ 13 ] the authors classified insect species on the basis of their sound signals. The prediction of unusual sound behavior of animals during earthquakes and natural disasters was studied using machine learning methods in [ 14 ]. Recently, the possibility of transfer learning from musical features for identifying bird sound using hidden Markov models (HMM) was investigated in [ 15 ].
Domestic animals have been close friends of humans since the time of human evolution, and they convey their messages by making certain identical sounds. Most domestic animals spend all their time in the vicinity of humans, so careful analysis of domestic animals is important. The domestic cat is one of the most beloved pets in the world, and according to a Live Science report (2013), the total population is about 88.3 million. The behavioral analysis of the domestic cat is well explained in [ 16 , 17 ].
An attempt at recognizing environmental sounds using HMM [ 18 ] shows the classification of 15 classes of different environmental sounds. Among the 15 classes there are also animal sounds (bird cries, dog barks and cat meows), which demonstrate better sound recognition accuracy using universal modeling based on GMM clustering than simple HMM and balanced universal modeling. The classification of domestic cat sounds using transfer learning [ 19 ] is the first step toward classifying cat sounds with limited data. Classifying cat sounds is an attempt to communicate better with the domestic cat and, therefore, perhaps to understand its intentions better.
This article is an extension of [ 19 ], which focuses on working with small datasets for the automatic classification of domestic cat sounds using machine learning algorithms. Data-driven approaches require class-labeled data, so our work begins with the creation of a small dataset of cat sounds. Our goal is to create a general-purpose domestic cat classification system that is independent of factors such as biodiversity, species and age variations, so we try to include many cat sounds in different moods. Since the collected dataset is insufficient, we increase the amount of data using various audio augmentation methods. As in [ 20 ], audio augmentation is performed by randomly choosing augmentation methods within the corresponding ranges of parameter values, as described in more detail in Section 3.1 .
Since little is known about which sound features are effective for our purpose, instead of hand-crafted features we use two types of learned features from deep neural networks: a convolutional neural network (CNN) and a convolutional deep belief network (CDBN). The CNN features are obtained from a network pre-trained on music data through transfer learning. Meanwhile, the unsupervised CDBN network features are extracted from a network trained solely on the collected set of cat sounds without class labels. We compare the two networks and their learned features in terms of the effectiveness of cat sound classification.
We try to classify cat sounds using five different machine learning algorithms, and finally combine their predictions to make the performance more robust. Each of these five algorithms is effective for classification tasks and requires less labeled data for training because of its small number of parameters. Cat sounds in each class have a different nature, which differs mainly in frequency ranges. To make our classification more effective, we also modify the usual global average pooling used for dimensionality reduction and call it frequency-divided average pooling (FDAP). FDAP first divides each feature map into different frequency bands and takes the average value in each band.
For classification, we use five different machine learning algorithms and their ensemble. We compare classification performance with respect to the following factors: the amount of data increased by augmentation, learned features from the pre-trained CNN or the unsupervised CDBN, ordinary global average pooling (GAP) or FDAP, five different machine learning algorithms, and their ensemble. As we expected, FDAP features with data increased by augmentation give the best accuracy in the ensemble approach. In addition, learned features from both the pre-trained CNN and the unsupervised CDBN give successful results in the experiment. Thus, with a combination of all these positive factors, we obtained the best result: 91.13% accuracy, 0.91 f1-score and 0.995 area under the curve (AUC).
This paper is organized as follows. Section 2 describes the preparation of the domestic cat sound dataset. Section 3 gives an overview of data preprocessing, extraction of CNN and CDBN network features, and classification of the extracted features. The results with discussion are included in Section 4. Finally, the conclusion and future work are mentioned in Section 5.
2. Cat Sound Dataset
Hearing is the second most important human sense after vision for recognizing any animal. Automatic recognition of cat sounds using data-driven machine learning requires a large amount of labeled data for successful training. Collecting sounds of domestic cats is a difficult task. The Kaggle challenge ( https://www.kaggle.com ) Audio Cats and Dogs provides 274 audio files with cat sounds, but they have no sound categories. Since there is no large sound dataset for the domestic cat, we collected one mainly from online video sources on YouTube ( https://www.youtube.com/ ) and Flickr ( https://www.flickr.com/ ).
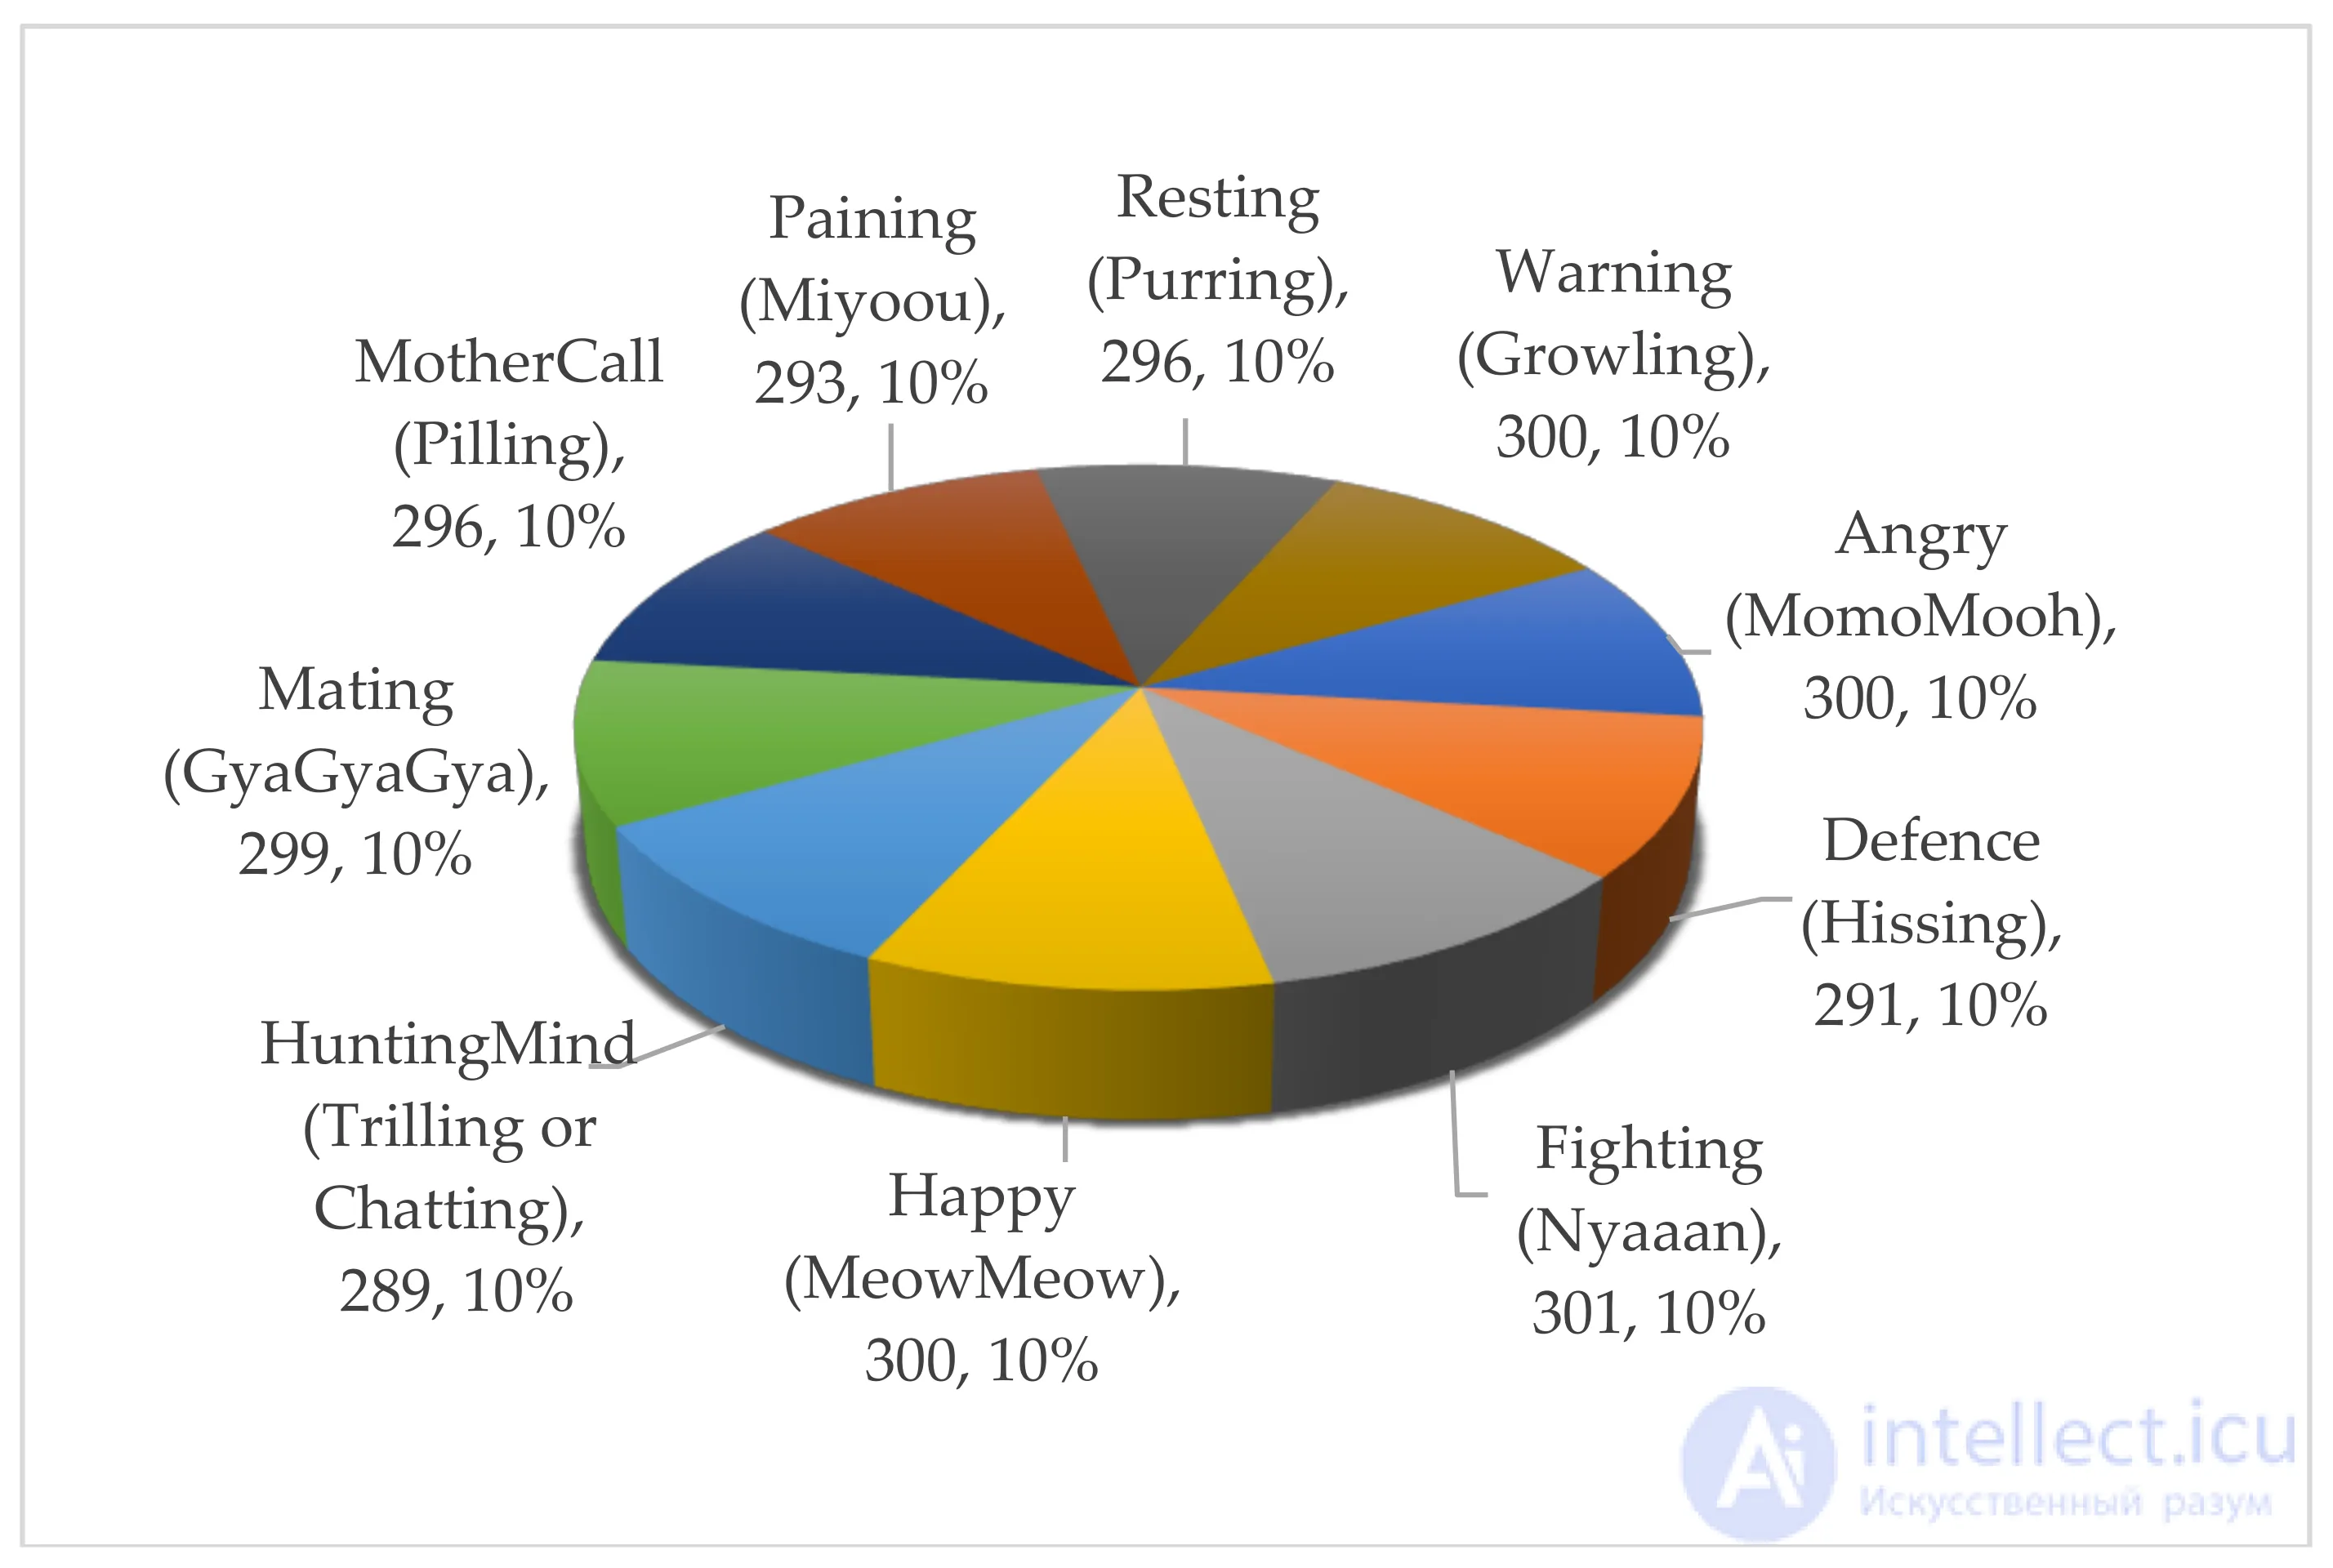
The pie chart in Figure 1 illustrates the cat sound dataset, named the CatSound dataset, where each class is named according to the cat's sound in various situations. The number of cat sound files in each class is about 300, which is about ten percent of the total number of data files, so our CatSound dataset is balanced. The total duration of the CatSound dataset is more than 3 hours for all sounds in 10 classes, which means that the average duration of a sound is about 4 seconds.
Figure 1. Balanced representation of the cat sound dataset. Each class in the dataset is named according to the mood or situation of the cat when it makes the sound. The onomatopoeic words in parentheses imitate the cat sounds in each class. The figures indicate the number of cat sounds, and the numbers with percentages indicate the corresponding share of each class size in the dataset.
Correct categorization of the collected sounds was another big problem, because some sounds in one category are very similar to those in other categories. In addition, cats often make different sounds with a small time difference. For example, an angry cat can make "growling", "hissing" or "nyaan" sounds almost simultaneously. The semantic explanation of domestic cat sounds in [ 21 , 22 ] helped us divide the various sounds into the appropriate classes.
Some audio files in our dataset were split into several segments of different lengths, each having the same semantic category, in the same way as in [ 23 ] for music information retrieval. For example, the sounds of a cat in a normal mood ("meow-meow"), defense ("hissing"), a kitten calling its mother ("pilling"), and cats in pain ("miyow") can be semantically correct even over a short time. On the other hand, the sounds a cat makes when resting ("purring"), warning ("growling"), mating ("gay-gay-gay"), fighting ("nyaan"), angry ("momo-mu"), and wanting to hunt ("trilling or chattering") are usually more meaningful if analyzed over a longer period of time. Even within some classes of cat sounds, the data may have different lengths, since biodiversity varies greatly with geographical location, cat breed and age. Waveform representations of 10 samples from each class are visualized in Figure 2. The graphic representation helps the reader understand the nature, amplitude and duration of the sounds.
Figure 2. Waveform visualization of 10 data samples taken from each class of the CatSound dataset.
3. Classification Method
This section covers data augmentation and preprocessing, transfer learning, frequency-divided average pooling, and feature extraction from our dataset. It also discusses the various classifiers and ensemble methods used in our work.
3.1. Data Augmentation and Preprocessing
Since the CatSound dataset is too small for training machine learning algorithms, it is necessary to increase the data size using proper data augmentation. In the experiment we performed audio augmentation as described in [ 20 ], using a random selection of augmentation methods with their parameters in the corresponding ranges. The augmentation methods include speed change (range from 0.9 to 1), pitch shift (range from -4 to 4), dynamic range compression (range from 0.5 to 1.1), noise addition (range from 0.1 to 0.5) and time shift (20% forward or backward). Note that each parameter should be chosen within a moderate range, otherwise the sound may be drastically altered and classified differently from the original sound.
The experiment uses three kinds of augmented datasets, namely 1x_Aug, 2x_Aug and 3x_Aug, as well as one original cat sound dataset. The 1x_Aug dataset contains the original data and its augmented clone. Similarly, the 2x_Aug and 3x_Aug datasets consist of the original audio file and its additional augmented clones, at twice and three times the size respectively. These four datasets (one original and three augmented) are prepared as input to the pre-trained CNN and the unsupervised CDBN for feature extraction.
Data preprocessing for feature extraction differs for each of the two neural networks because of the difference in their structure. The first step of our input processing is zero padding, to create a full-length sound that can generate a mel spectrogram of fixed size. The role of zero padding in a time-domain signal is to increase frequency resolution and to create full periods in the signal, which eliminates spectral leakage. Discrete cat sound signals sampled at 16 kHz are represented as a mel spectrogram as the input to both networks. For the CNN, mel spectrograms are extracted from each cat sound dataset using the Kapre method [ 24 ]. The input to the CNN has one channel, 96 mel bins and 1813 time frames. In the case of the CDBN, a mel spectrogram with 96 mel bins and 155 time frames is prepared for input after whitening. The preprocessing procedures for the CNN and CDBN networks are shown in Figure 3.
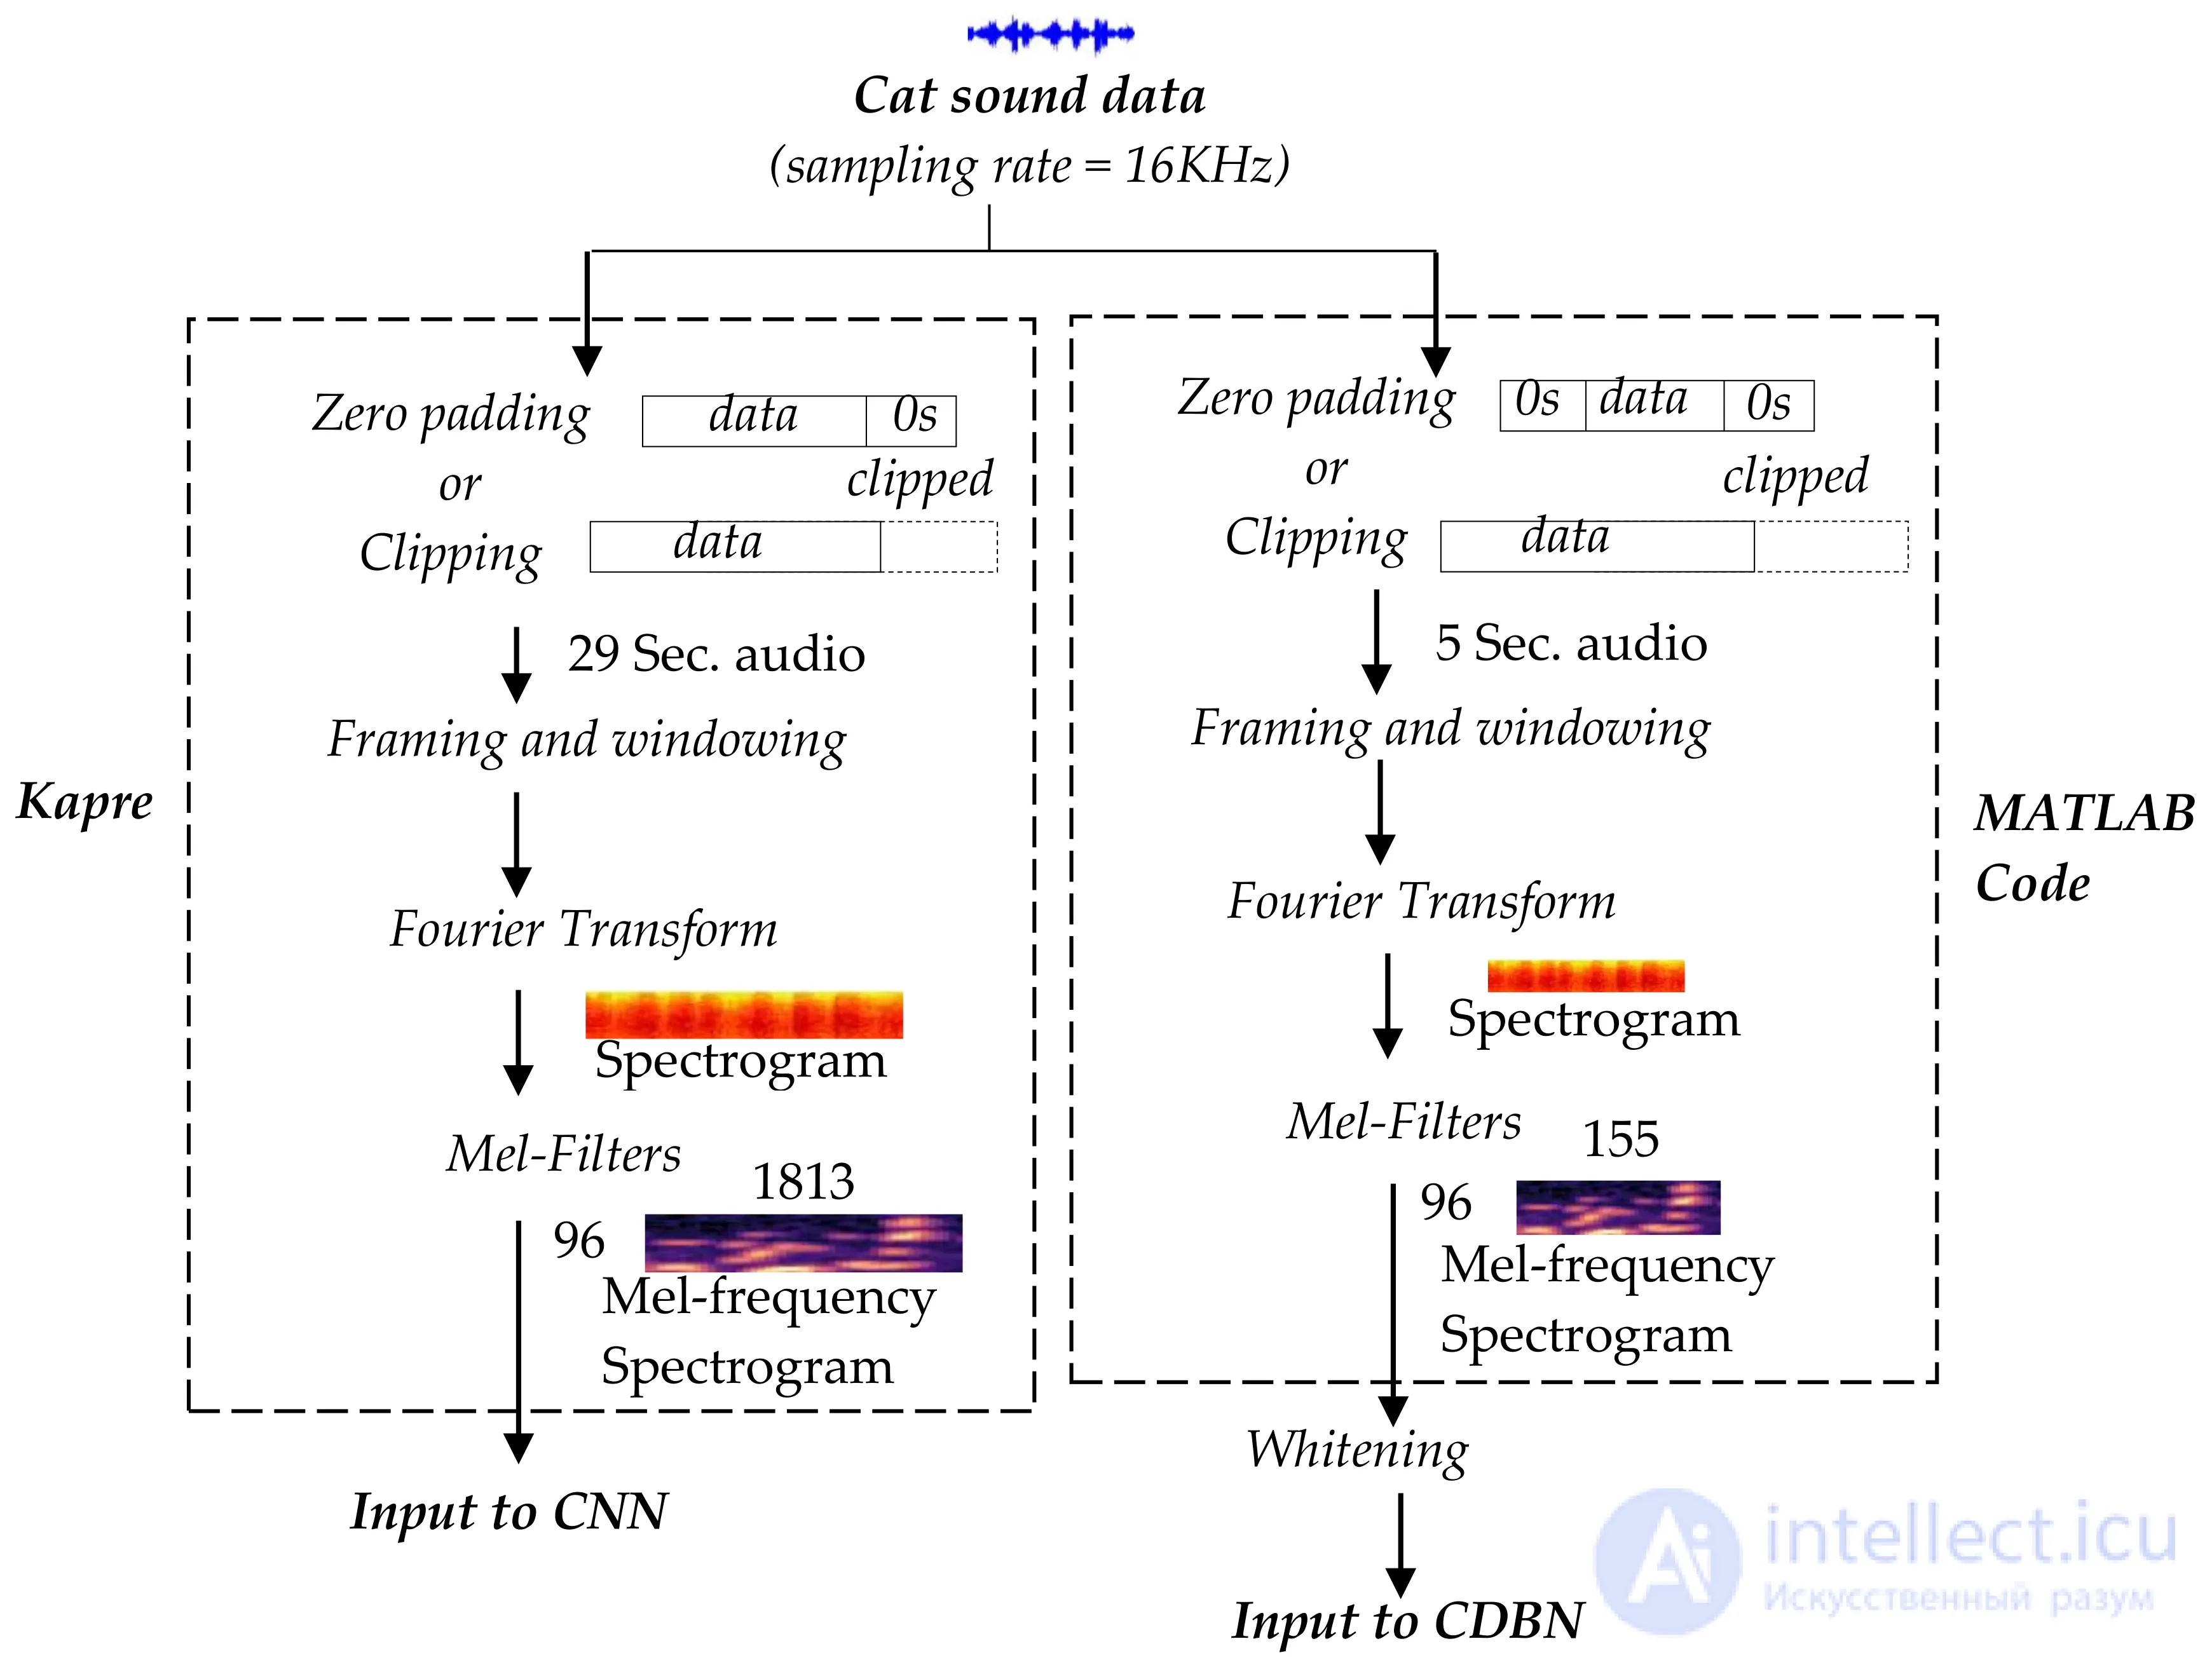
Figure 3. Input preprocessing for the convolutional neural network (CNN) ( left ) and the convolutional deep belief network (CDBN) ( right ). For the CNN input, all preprocessing is performed using Kapre, and short audio data are zero-padded only on the right side. MATLAB code is used for preprocessing the CDBN input, and short audio data are zero-padded on both sides. Finally, whitening is performed at the end.
3.2. Frequency-Divided Average Pooling
Conventional GAP layers vectorize the feature maps of a convolutional network, as described in [ 25 ]. GAP is a dimensionality reduction method that reduces a three-dimensional tensor to a single feature vector by taking the average of each feature map. For example, if the tensor has dimensions H × W × C , then GAP reduces the size to 1 × 1 × C , where H , W , C are the height, width and channel of the tensor, respectively. One of the main advantages of using GAP is the reduction of network parameters, since there are no parameters to optimize.
In this work we used frequency-divided average pooling, which is a modified version of GAP. This is region-specific feature extraction, where we first divide the feature map into low-frequency and high-frequency bands and then apply GAP in each band. This is an effective way of handling frequency-varying data such as cat sounds, in which frequency components in a certain band are active for certain classes of sounds. The log-power spectrogram and mel spectrogram of data samples taken from each class of the CatSound dataset, as shown in Figures 4 and 5, indicate that the activity of cat sounds in frequency ranges differs depending on the sound class. Therefore, if the features are properly segmented into several frequency bands, we can expect better classification performance. However, it is difficult to determine exact cut-off points for dividing feature maps into frequency bands, so we overlap the frequency division, like the overlapping windows of the short-time Fourier transform (STFT). Features are taken by overlapping a small part (a single bin) of adjacent frequency components. There may be many alternative ways of dividing the feature maps of networks into frequency bands. We divide the feature maps according to the number of frequency components available in each layer, and hence a higher-level feature map has a relatively smaller number of divisions.
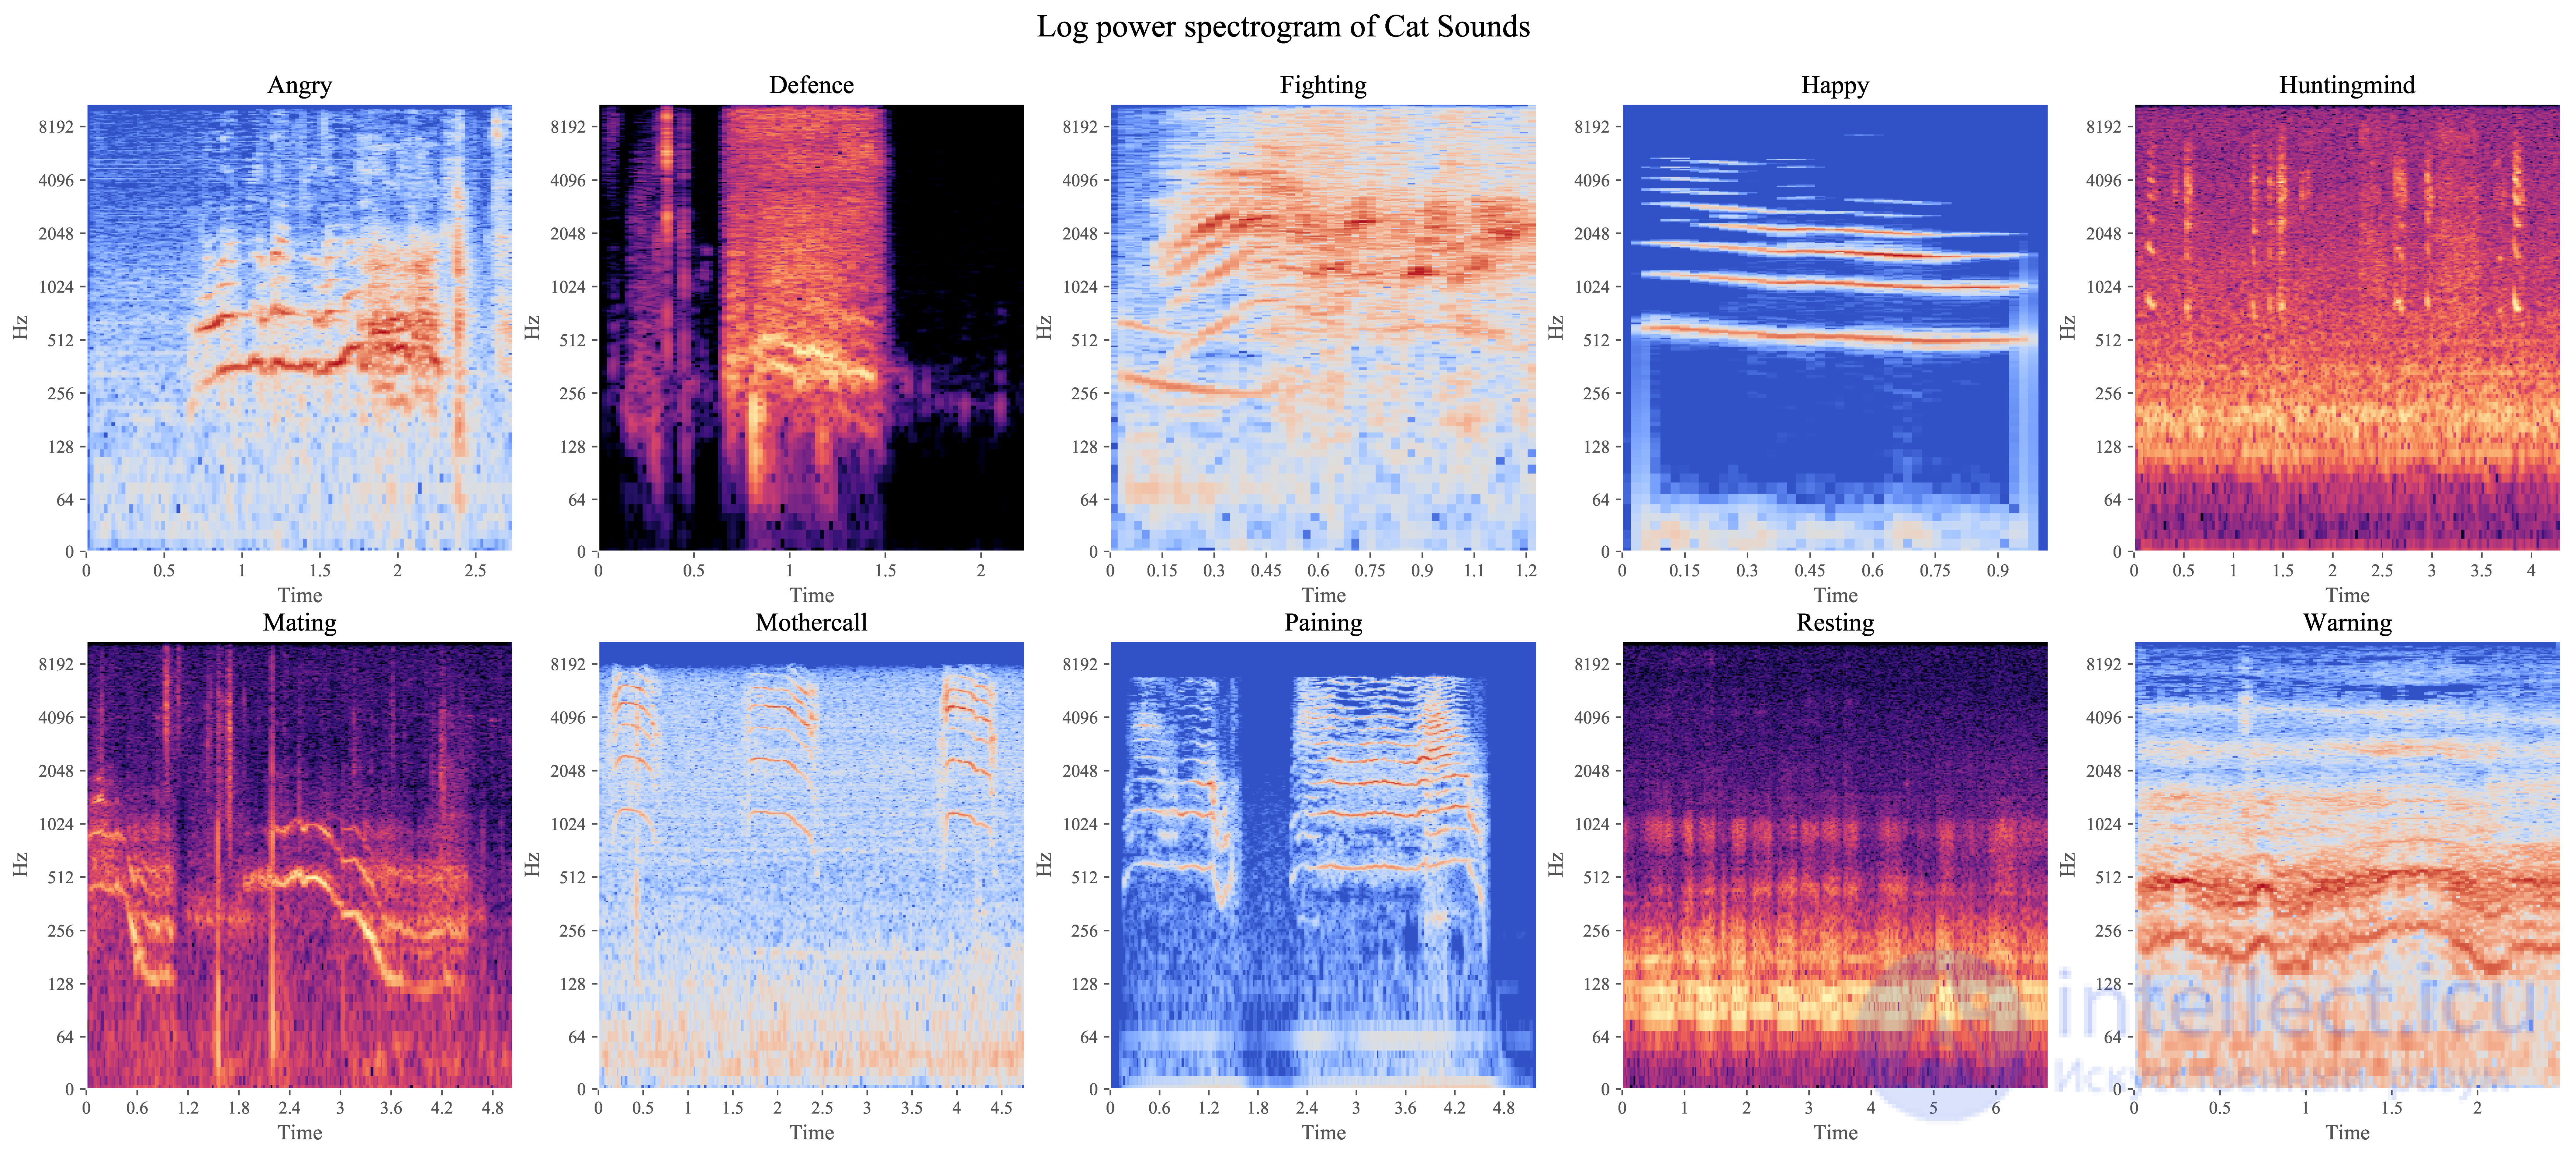
Figure 4. The sample in Figure 2 converted to a log-power spectrogram.
Figure 5. The sample in Figure 2 converted to a mel spectrogram.
3.3. CNN Transfer Learning
Transfer learning is the process of transferring any knowledge gained from one or more source domains to a target domain, so that the target can generalize its predictive ability to solve similar problems. A key advantage of transfer learning is improved performance with a small amount of labeled training data. This is possible if the source and target networks have similar tasks. A recent study of transfer learning in music onset detection [ 26 ] shows that a difference between the source and target datasets can make it impossible to capture relevant information when using transfer learning. The transfer learning technique has been successfully applied and studied in various research areas, such as image classification [ 27 , 28 ], acoustic event detection [ 29 , 30 ], speech and language processing [ 31 ] and music classification [ 32 , 33 ].
However, in this work there is no useful alternative to transfer learning for compensating for the lack of data. Therefore, a CNN pre-trained on the Million Song Dataset [ 34 ] is adopted as a feature extractor, and we test the effectiveness of the feature learned from music for cat sound classification. The features from the network [ 33 ] obtained by transfer learning show good results in music classification and regression. Although cat sounds differ in some respects from studio-recorded music in terms of frequency variation, signal-to-noise ratio, abrupt changes in intensity and frequent interruption by environmental sounds, some follow-up studies show a close relationship between music and animal sound. In Western classical music, composers and musicians have commonly used birdsong in various ways [ 15 , 35 , 36 ] [ 37 ]. In addition, the sounds of domestic and wild animals are also directly or indirectly included in songs [ 36 ] to create background noise in concert halls [ 35 ]. A review study [ 38 ] illustrates the close relationship between human languages, (human) music and animal vocalization. In conclusion, the diversified music in the Million Song Dataset has some connection with cat sound, and this may be one solution to the problem of the lack of data in cat sound classification if transfer learning is performed. Consequently, we use the pre-trained CNN as the source network for transfer learning.
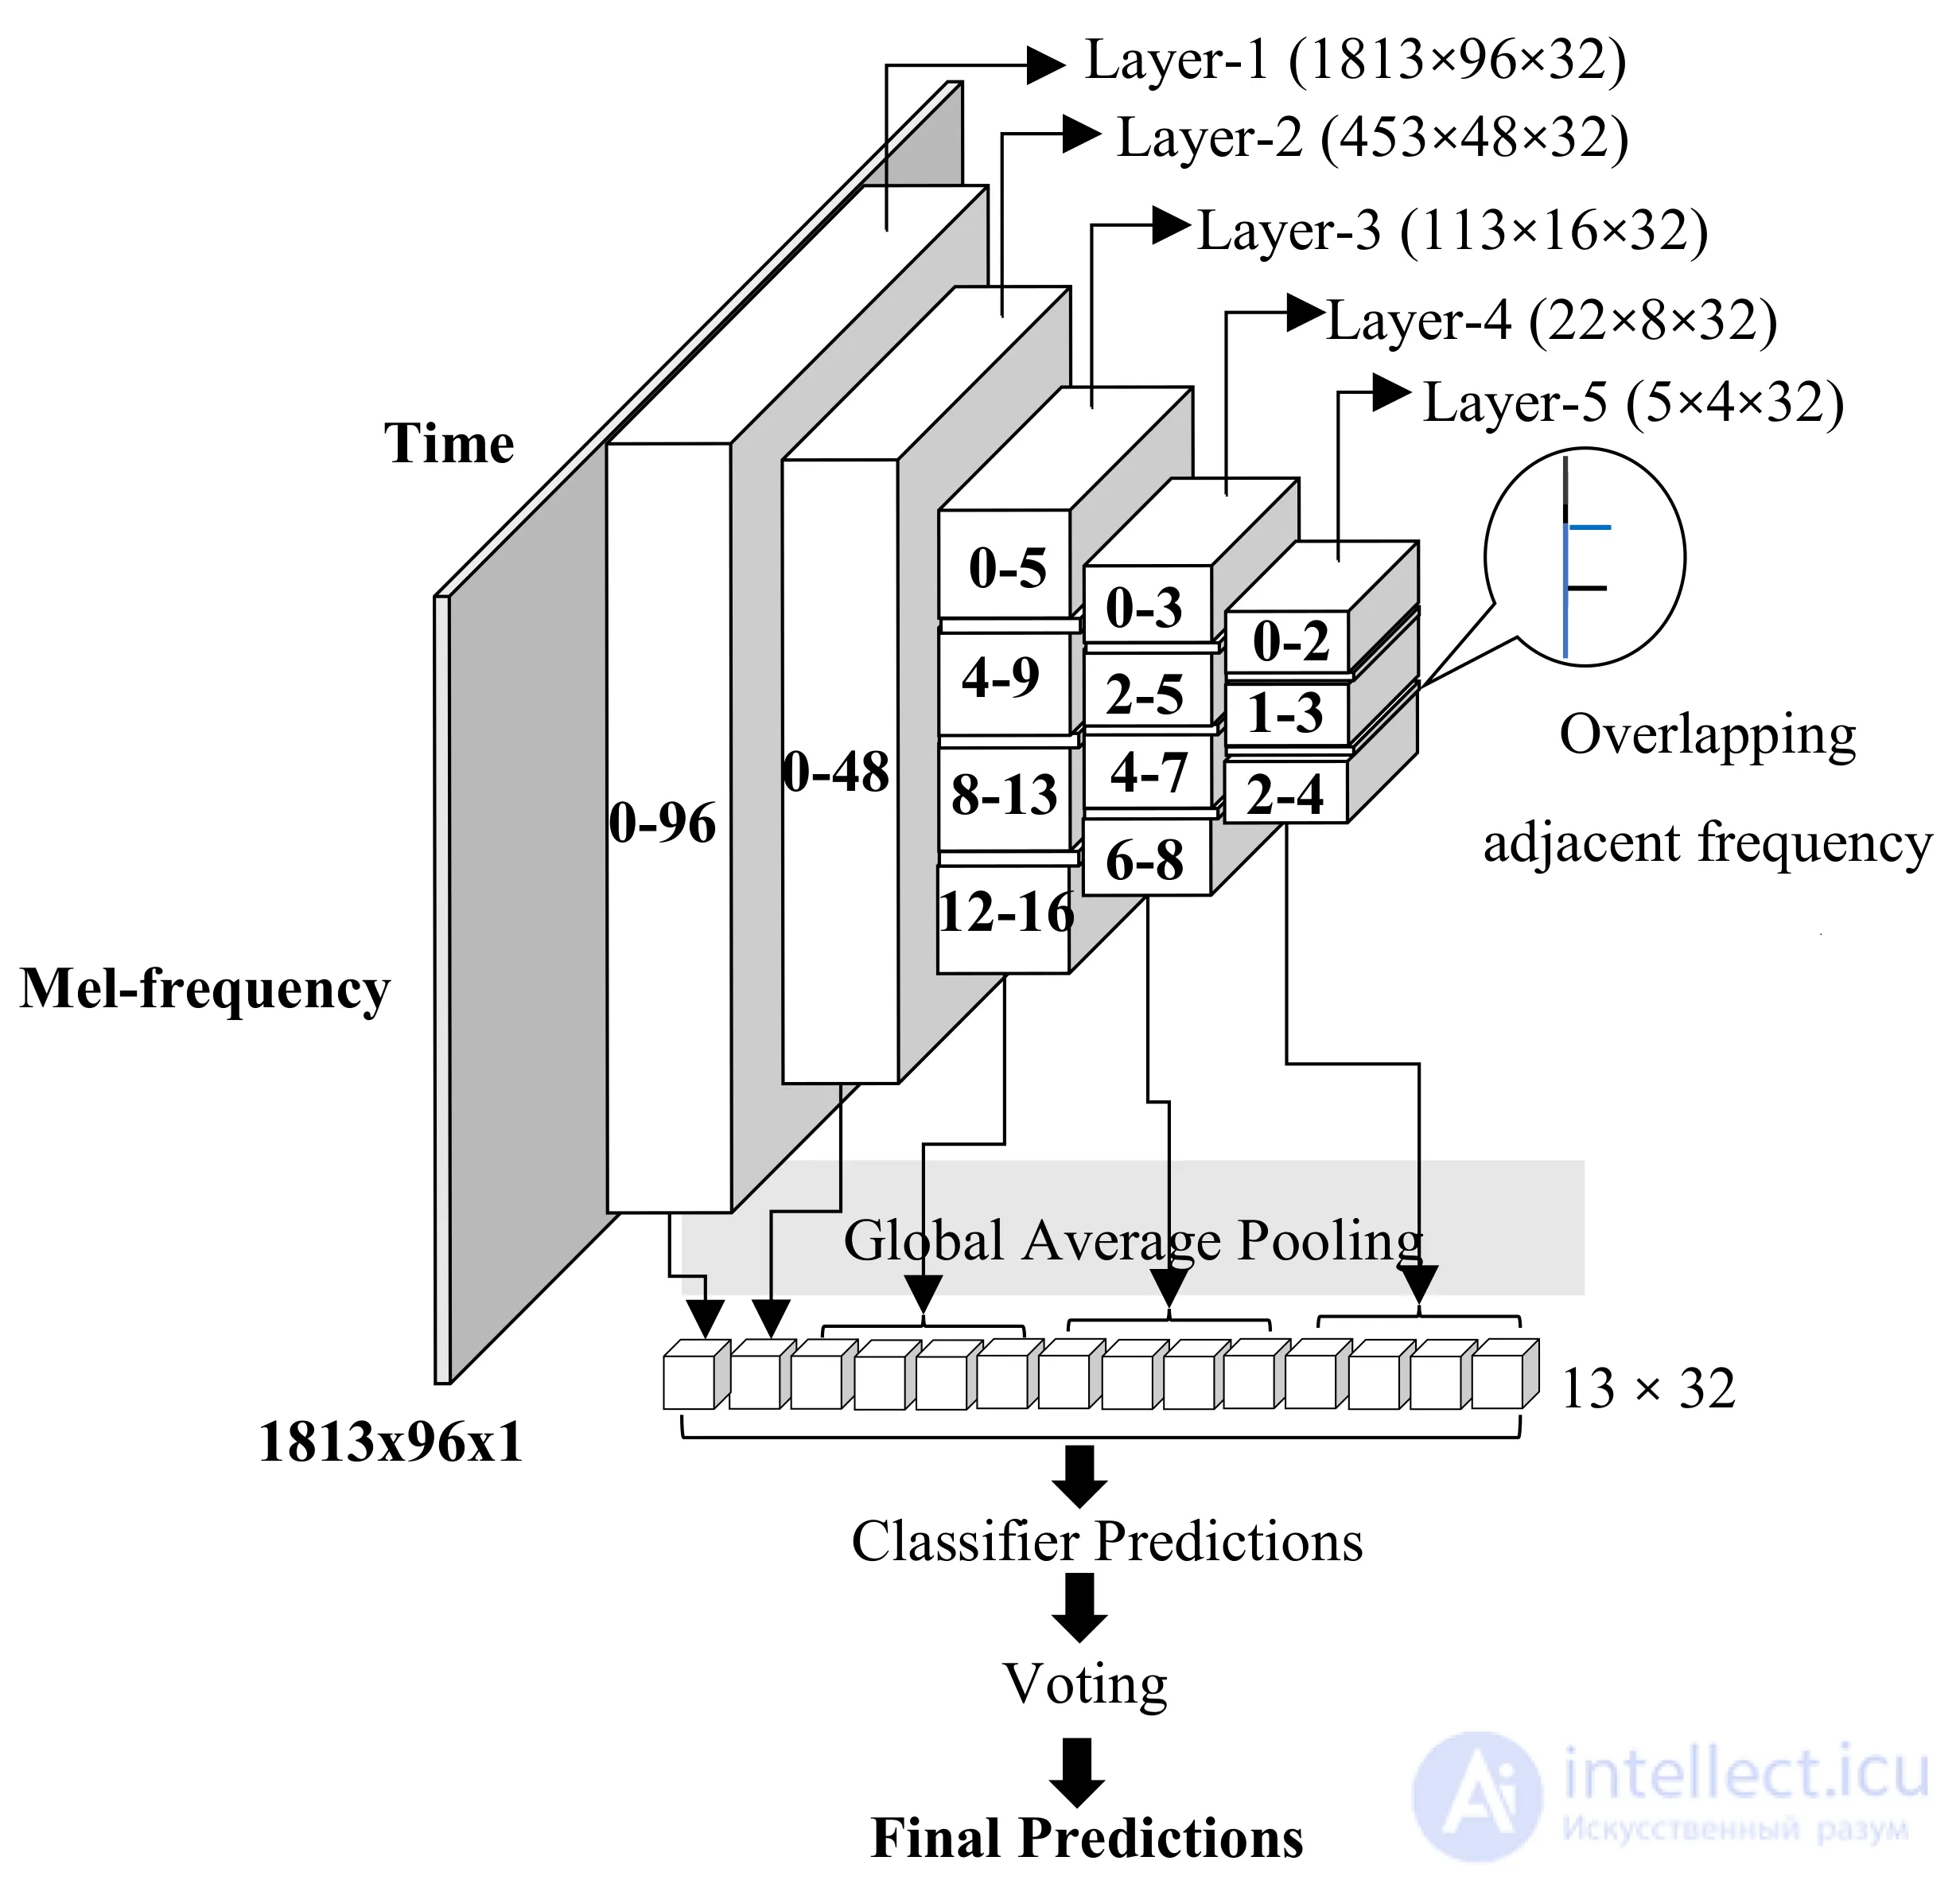
We extracted features from this pre-trained network for both the original and augmented datasets using Keras ( https://keras.io/ ). The large dimensions of the features extracted in each layer are reduced to a vector using the FDAP method and then concatenated. All experiments were run on an NVIDIA GeForce GTX 1080 Ti graphics processor. We encountered a memory problem when extracting features from the first two layers, and therefore we inevitably used ordinary global average pooling in these two layers. To apply FDAP to the third and fourth layers, the feature maps are divided equally into four bands. But the feature maps of the fifth layer are divided into two overlapping bands, because there is only a small number of bins in the mel frequency dimension. Each band has 32 features, and all of them are concatenated to create the input vector for the five classifiers. Feature extraction and classification using the pre-trained CNN architecture are shown in Figure 6. The experimental results show that even though cat sound and music differ greatly, the audio signals have similar characteristics, so transfer learning is useful.
Figure 6. CNN transfer learning and classification of the extracted features. From the first to the fifth layer, the number of segments for frequency-divided average pooling (FDAP) in each layer is 1, 1, 4, 4 and 3, respectively. The parameters of each layer are given as ( time × frequency × channel ). Each segment produces a 1 × 32-dimensional feature vector, and the concatenated feature vector is fed into various classifiers, with voting on the predicted probability for the final ensemble result.
3.4. CDBN Feature Extraction
Convolutional restricted Boltzmann machines (CRBM) [ 39 , 40 ] are the building blocks of the CDBN, and a CRBM is an extension of the RBM [ 41 ] to a convolutional setting. The CDBN is an unsupervised hierarchical generative model for extracting features from unlabeled visual data [ 42 ] or acoustic signals [ 43 ] using a layer-wise greedy bottom-up approach. Inspired by these studies, we built a five-layer CDBN architecture, as shown in Figure 7. Spectral whitening in the frequency domain is performed on the fixed-size mel spectrogram before feeding it into the CRBM, and the features extracted from each layer are the input to the corresponding higher layer of the network. Filters of various sizes are used, namely [3 × 7], [3 × 3], [3 × 3], [3 × 3] and [3 × 3] with a fixed pooling size of [2 × 2], for the five successive CDBN layers, respectively, where the size is denoted as [frequency resolution bins × frames].
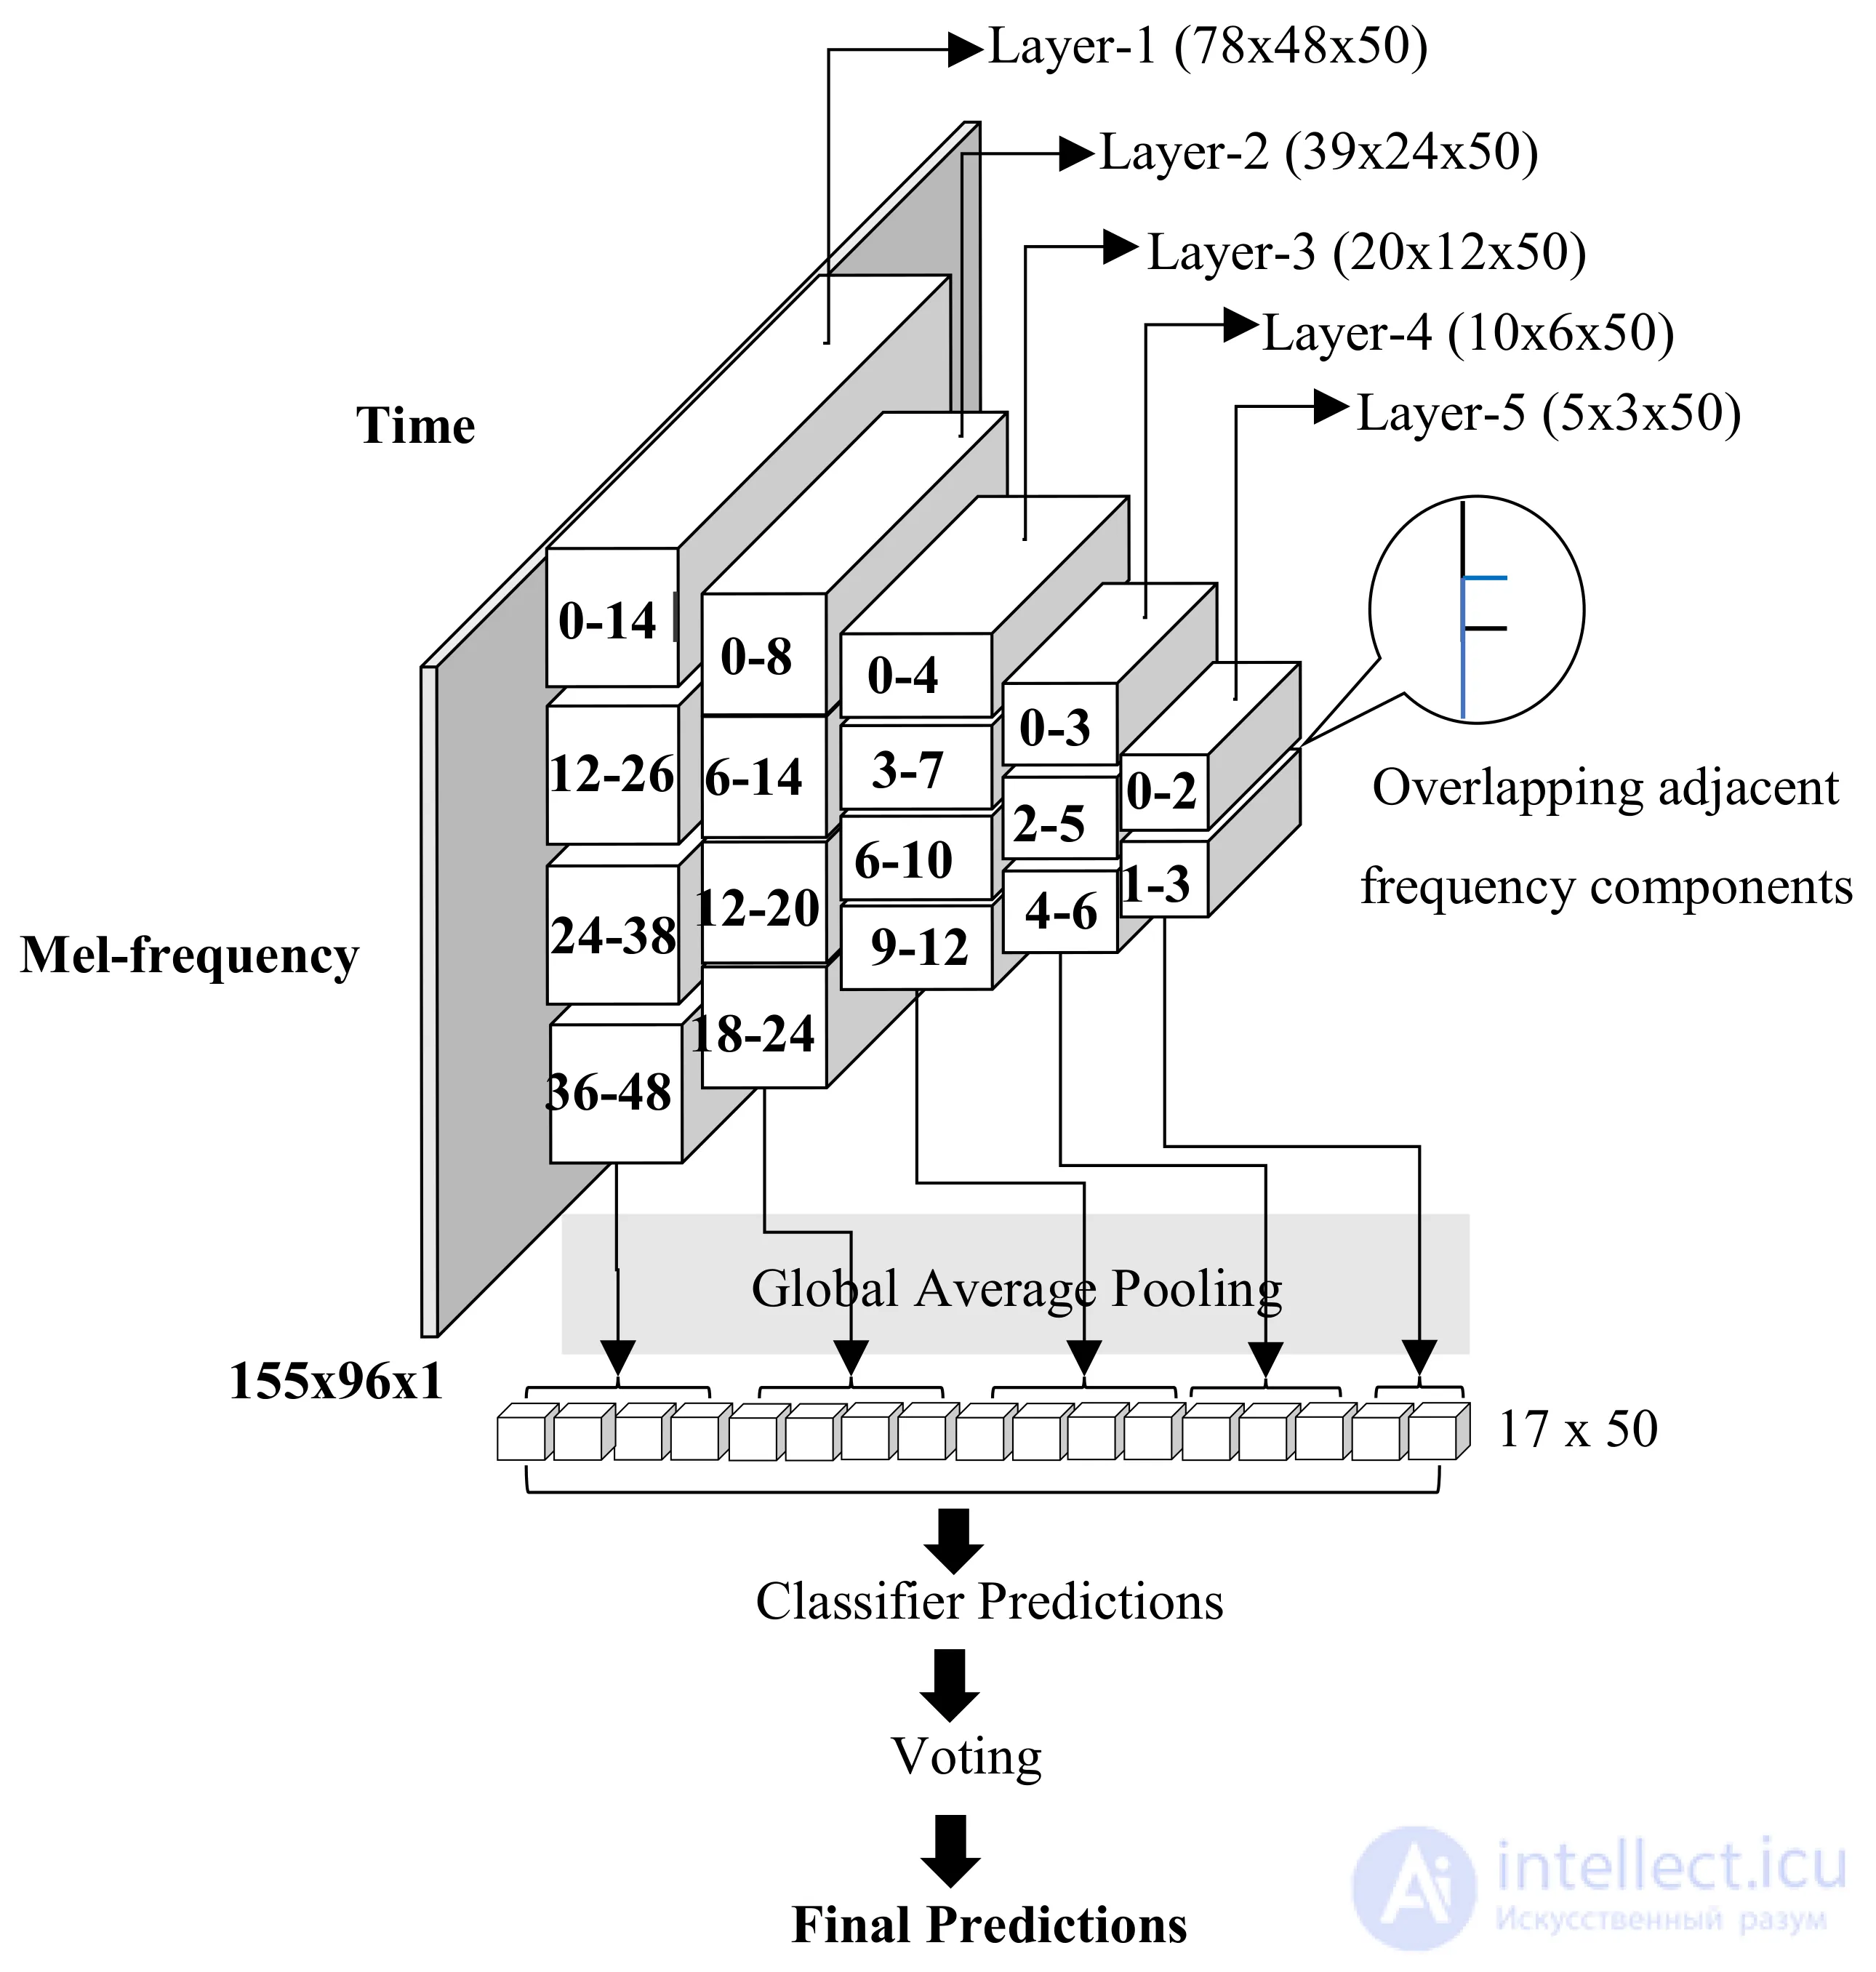
Figure 7. Overview of feature extraction from the CDBN network and classification. Features from each layer are extracted using overlapping FDAP, shown in each segmented feature block. The parameters of each layer are given as ( time × frequency × channel ). The concatenated feature vector is fed into various classifiers, with voting on the predicted probability for the final ensemble result.
The CDBN is trained solely on cat sound data, and the features of each layer are saved for further classification. The feature map of each layer is divided for FDAP, and then the feature vectors are concatenated to be fed into the classifiers. The CDBN features are divided by frequency range with overlap. The first three layers are divided into four equal bands, while the features of the fourth and fifth layers are divided into three and two bands, respectively. Concatenating 50 features from each band of the layers results in a feature vector of size 1 × 850. This feature vector is the input to the five classifiers, and the prediction results are combined with equal priority to obtain the final predictions by voting. The learned CDBN features are shown in Table 1.
Table 1. Visualization of the learned feature of the first channel of the proposed CDBN network at each layer. The waveform of the same data sample is presented in Figure 2.
3.5. Classification of Cat Sounds
We chose five classifiers provided in the Python sklearn library ( http://scikit-learn.org ) to classify cat sounds using the learned features of the pre-trained CNN and the unsupervised CDBN. These machine learning algorithms are powerful and can work well even with a limited amount of labeled data. Here we give a brief introduction to the classifiers used in this work. The random forest (RF) classifier [ 44 ] uses a majority voting scheme ( Bagging [ 45 ] or Boosting [ 46 ]) to make the final prediction based on a predefined number of decision trees. The K-nearest neighbor (KNN) [ 47 ] classifier finds the class to which an unknown object belongs using the majority vote of the k nearest neighbors. The extremely randomized trees (or Extra Tree) [ 48 ] classifier tries to randomly find the optimal cut-off point for each given feature. Linear discriminant analysis (LDA) [ 49 ] is an extension of the idea of Fisher's discriminant analysis [ 50 ] to situations with any number of classes, and uses matrix algebra tools for its computation. LDA is a type of Bayesian classifier that requires the assumption of equal class variance-covariance matrices. The support vector machine [ 51 ] (SVM) classifier with a radial basis function (RBF) kernel is used in this study for nonlinear classification of the features we extracted. Comparative results of these classifiers are given in Section 4.
An ensemble is a well-known machine learning technique that combines the predictive abilities of several classifiers and then classifies new data points by taking a (weighted) vote of their predictions, as experimentally proven in [ 52 ] for sound classification purposes. A number of recent algorithms have been developed, such as bagging, bucket of models, stacking and boosting. The ensemble method combines several machine learning methods into one predictive model in order to reduce variance (bagging), reduce bias (boosting) or improve predictions (stacking) [ 53 ]. In this experiment we choose the simplest majority vote with equal priority for the ensemble of our five classifiers.
4. Results
To evaluate performance and accuracy, we used the F1 score [ 54 ] and the area under the receiver operating characteristic curve (ROC-AUC) [ 55 ]. Accuracy is the percentage of correctly classified samples of unseen data, while the F1 score is the harmonic mean of precision and recall [ 56 ]. The ROC-AUC score is measured for each classifier on the receiver operating characteristic (ROC) curve [ 55 ]. The ROC curve is used to visualize and analyze the performance of each classifier across the different decision thresholds associated with it. The confusion matrix shows the exact performance for the different classes.
In the experiment we used 10-fold cross-validation [ 57 ] to evaluate performance under the different configurations of the experimental setup. We then compared performance across the following factors: the amount of data increased by augmentation, the features learned from a pre-trained CNN or from an unsupervised CDBN, conventional GAP or FDAP, five different machine learning algorithms, and their ensemble.
The evaluation results show that augmenting the dataset, the FDAP method, and majority voting over the classifier predictions improve overall performance and reduce confusion, as we expected. Table 2 shows the best results of the different classifiers using the two types of learned features with the 3x_Aug dataset.
Table 2. Best performance of the different classifiers for CNN and CDBN features extracted from the 3x_Aug dataset with FDAP. Bold numbers mark the highest score of the algorithm(s) for the features learned from the network.
Table 2. Best performance of the different classifiers for CNN and CDBN features extracted from the 3x_Aug dataset with FDAP. Bold numbers mark the highest score of the algorithm(s) for the features learned from the network.
| Classifiers |
Accuracy (%) |
F1-Score |
AUC Score |
| CNN (± SD) |
CDBN (± SD) |
CNN |
CDBN |
CNN |
CDBN |
| RF |
84.64 (0.02) |
86.32 (0.03) |
0.85 |
0.86 |
0.988 |
0.988 |
| KNN |
81.60 (0.02) |
80.32 (0.02) |
0.82 |
0.80 |
0.898 |
0.890 |
| Extra Trees |
83.80 (0.03) |
84.29 (0.03) |
0.84 |
0.84 |
0.987 |
0.985 |
| LDA |
78.48 (0.02) |
81.84 (0.03) |
0.78 |
0.82 |
0.975 |
0.979 |
| SVM |
87.43 (0.03) |
90.88 (0.04) |
0.87 |
0.91 |
0.992 |
0.994 |
| Ensemble |
90.80 |
91.13 |
0.91 |
0.91 |
0.994 |
0.995 |
SD - standard deviation over the cross-validation folds.
Note that the features learned from the pre-trained CNN trained on music gave results comparable to those from the unsupervised CDBN, which is trained exclusively on cat sound data. The SVM classifier also performs well on the CDBN features, but its AUC score does not exceed that of the ensemble classifier.
The results of the ensemble classifier with and without augmentation, and with the GAP or FDAP implementation, are presented in Table 3 . Note that the performance of the classifiers improved consistently as the amount of training data was increased through augmentation, regardless of the neural network used for feature extraction. In addition, FDAP gives better performance than conventional GAP in all comparisons, which shows that FDAP is more effective for classifying cat sounds. The average gain in prediction accuracy on the cat sound dataset using FDAP is 7.37 for the CNN and 10.05 for the CDBN when the 3x_Aug dataset is used for training.
Table 3. Accuracy, F1 score and area under the ROC curve for comparing the CNN and CDBN using the ensemble classifier on the original and augmented datasets. The advantage of FDAP over GAP on the feature map of each layer of the two networks using the different datasets is indicated by "GAP" and "FDAP" at the end of the corresponding dataset name. Bold numbers mark the most effective algorithms for the dataset using FDAP in the learned features of the network.
.
| Cat Sound Dataset |
Accuracy (%) |
F1-Score |
AUC Score |
| CNN |
CDBN |
CNN |
CDBN |
CNN |
CDBN |
| Original_GAP * |
70.71 |
76.09 |
0.690 |
0.760 |
0.958 |
0.963 |
| Original_FDAP # |
79.12 |
82.15 |
0.780 |
0.820 |
0.974 |
0.982 |
| 1x_Aug_GAP |
80.61 |
76.39 |
0.810 |
0.760 |
0.977 |
0.970 |
| 1x_Aug_FDAP |
86.51 |
87.52 |
0.860 |
0.880 |
0.989 |
0.989 |
| 2x_Aug_GAP |
81.89 |
76.60 |
0.820 |
0.760 |
0.982 |
0.969 |
| 2x_Aug_FDAP |
89.31 |
87.96 |
0.890 |
0.880 |
0.993 |
0.991 |
| 3x_Aug_GAP |
83.04 |
79.49 |
0.830 |
0.790 |
0.985 |
0.977 |
| 3x_Aug_FDAP |
90.80 |
91.13 |
0.910 |
0.910 |
0.994 |
0.995 |
* GAP—Global average pooling; # FDAP—Frequency division average pooling.
Table 4 shows the confusion matrix of our best ensemble classifier using CDBN learned features with the 3x_Aug dataset. Using this confusion matrix, we examined the benefits of the FDAP method over conventional GAP. The off-diagonal numbers represent the number of cat sounds in each class that are misclassified by the ensemble classifier. By analyzing the confusion matrix of each of the five classifiers and of the ensemble classifier, we can draw several conclusions. Defense ("hissing") and HuntingMind ("trill or chatter") sounds are easy to distinguish from other cat sounds, at least in our CatSound dataset, so these classes are relatively less confused. On the other hand, Happy ("meow-meow") and Paining ("miyoou") have some similarity in their acoustic characteristics, so all the classifiers find these classes more confusing. Similarly, Warning ("growl") is easily confused with Mating ("gay-gay-gay").
Table 4. Confusion matrix of the best ensemble classifier for the 3x_Aug dataset using CDBN features with GAP and FDAP. The first number represents the number of confused cat sounds when GAP is used, and the second when FDAP is used, shown in the format GAP / FDAP.
| Angry |
Defense |
Fighting |
Happy |
HuntingMind |
Mating |
MotherCall |
Paining |
Resting |
Warning |
| Angry |
83 * / 94 # |
2 / - |
2 / - |
- / - |
- / - |
2/1 |
1 / - |
4/1 |
- / - |
7/4 |
| Defense |
1 / - |
92/97 |
- / - |
- / - |
4/1 |
1/3 |
1 / - |
- / - |
- / - |
1 / - |
| Fighting |
1/1 |
2 / - |
84/90 |
1 / - |
7/5 |
1/1 |
- / 2 |
3/1 |
- / - |
1/1 |
| Happy |
4/2 |
4/2 |
3 / - |
74/90 |
5/1 |
1 / - |
1/1 |
1/1 |
- / - |
- / - |
| HuntingMind |
1 / - |
4 / - |
4/1 |
- / - |
78/96 |
6/1 |
- / - |
- / - |
2 / - |
6/2 |
| Mating |
2/2 |
- / - |
2/1 |
- / 2 |
7/3 |
76/85 |
1 / - |
2/2 |
2 / - |
8/5 |
| MotherCall |
1 / - |
- / - |
2 / - |
4/2 |
4/2 |
3/1 |
78/94 |
4 / - |
5/2 |
- / - |
| Paining |
7/5 |
1 / - |
3/1 |
8/4 |
1/2 |
1 / - |
4/3 |
75/85 |
- / - |
- / - |
| Resting |
- / - |
3/3 |
1 / - |
- / - |
6/3 |
4 / - |
1 / - |
- / - |
78/92 |
7/1 |
| Warning |
5/2 |
5/2 |
2 / - |
1/2 |
4/2 |
5/2 |
- / - |
1/1 |
2/1 |
76/89 |
* Number of cat sounds falling into the same or a different class using GAP; # Number of cat sounds falling into the same or a different class using FDAP.
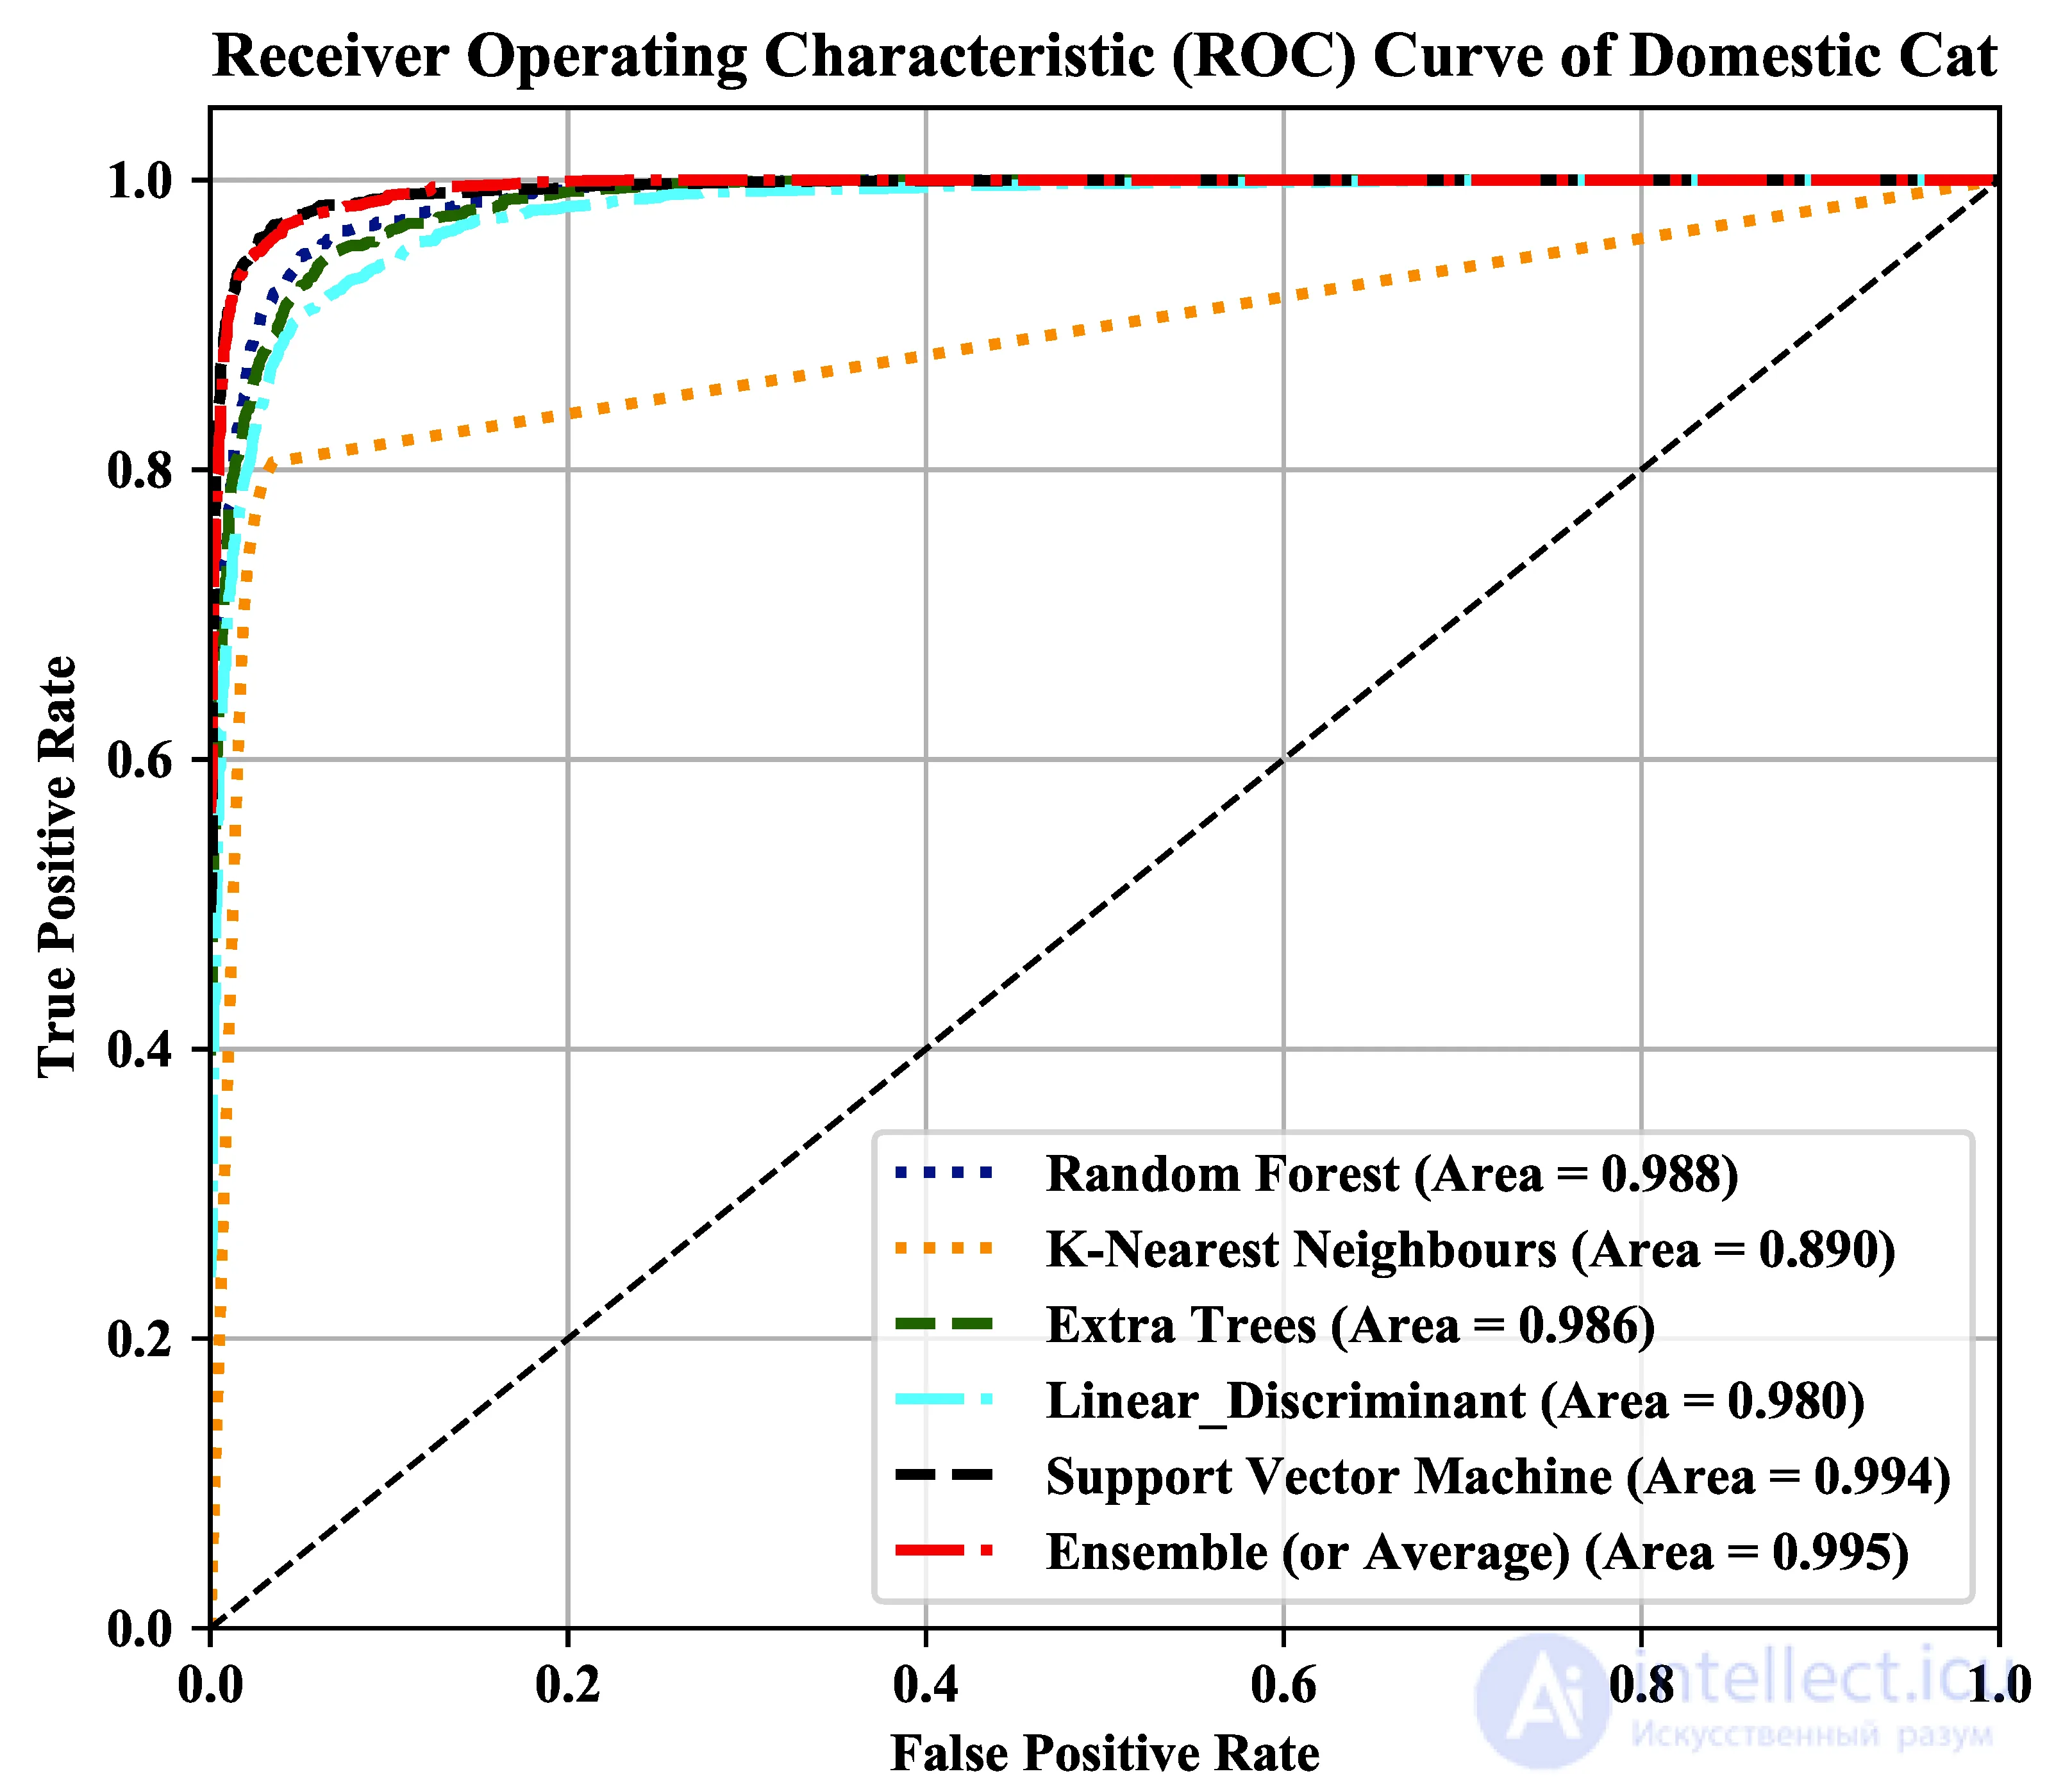
The ROC curves of the five classifiers and the ensemble classifier, with their corresponding ROC-AUC scores, are shown in Figure 8 . It can be seen that the ensemble classifier delivers performance closest to that of an ideal classifier, even though the SVM shows similar performance.
Figure 8. ROC curves of the different classifiers with the 3x_Aug datasets using CDBN features. Each curve is shown in a unique color, and the corresponding AUC score is given in parentheses.
5. Discussion
The features of the unsupervised CDBN lead to higher classification accuracy than the features from the pre-trained CNN, except for the case of 2x_Aug_FDAP, as shown in Table 2. There may be several reasons. First, the CDBN features are learned exclusively from cat sounds, while the CNN features come from a network pre-trained on music data. Nevertheless, we can conclude that transfer learning still works even when the source and target tasks differ slightly. Another reason is that the FDAP method was applied to the last three layers of the CNN, whereas it was used on all layers of the CDBN. In conclusion, the performance improvement of the CNN using FDAP is relatively higher than that of the CDBN. In the future, performance is expected to improve if FDAP is applied to all layers.
CDBN features may perform better if more training data is available. In comparing the classifiers, the SVM classifier predicts more accurately than the other classifiers, but it requires relatively more training time. As mentioned earlier, the ensemble classifier gives the best accuracy in all the various configurations of the experimental setup.
Conclusions
Classifying the sounds of domestic cats is an attempt to improve interaction between pets and humans. A well-founded, data-driven classification approach requires a large amount of class-labeled data. In this work, we first created a small cat sound dataset with 10 categories and visualized the sound characteristics in terms of their temporal and frequency representations. We hope this dataset can inspire other researchers to study a similar task. We expanded this small dataset by choosing various audio augmentation methods. In addition, we modified the traditional concept of global average pooling (GAP) and used frequency division average pooling (FDAP) to better learn and exploit the learned features of deep neural networks.
This study experimentally examines the effect of data augmentation and FDAP. Another way to overcome the limited availability of large annotated data for cat sound classification is transfer learning. We found that even though the source CNN was trained on music data, it is still useful to extract learned features from a small cat sound dataset using transfer learning. The unsupervised CDBN architecture is another way to extract learned features. The features of the unsupervised CDBN network, trained exclusively on cat sound data, perform slightly better than the features from the CNN trained on music data. Our FDAP method was applied only to the last three layers of the CNN, so there is room for improving performance in the future. We also compared the performance of five different classifiers and their ensemble. Finally, we can conclude that data augmentation, majority voting by the ensemble, and FDAP are ways to improve classification performance for a small cat sound dataset.
Clearly, our work is not free of limitations either. The dominant limitations may be the lack of expert involvement in labeling the cat sound data, biases in the pre-trained CNN and CDBN, the lack of data, and transferring learning between two different datasets.
In the future, results may be improved if a large labeled dataset becomes available for end-to-end training of the network. Different schemes for dividing feature maps in the layers of a deep neural network may improve classification performance. In addition, for accurate data labeling it would be better to consult cat vocalization specialists. Here we used a CNN pre-trained on music data, which differs somewhat from cat sound. If there were a pre-trained network trained on animal sound similar to cat sound, transfer learning could give better classification results. Analyzing the cat sound signal with another type of machine learning algorithm, such as the extreme learning machine (ELM) or multi-kernel ELM (MKELM) [ 58], are possible methods for a more comparative study in the future.
See also
- neural network ensemble
- deep learning
- perception
- sensations







Comments